阅读视图

发现新文章,点击刷新页面。
✇Tomshardware

Developer vibe codes a tool to let Nvidia RTX 50-series laptop owners crank up their power limits — can juice RTX 5090 mobile GPU to 225W

作者 Zak Killian

Folks with Nvidia-based gaming laptops can now use a new tool called NvpwrControl to unlock additional performance from their assuredly power-limited mobile GPU, as long as they're willing to accept the risks of cranking their GPU power limit by as much as 40 watts. The tool, spotted by VideoCardz, is available for download on GitHub, and it is labeled as 'experimental', so you'll want to be very sure you're willing to damage the reliability, if not the lifespan, of your fancy discrete GPU gaming laptop before using it.

If you've ever had a gaming laptop, you will know that the GPU model name can be deeply misleading. Whether it's NVIDIA using wildly different GPU configurations, AMD using confusing suffixes that don't exist in desktop GPUs, or Intel naming integrated graphics like a discrete GPU, all three vendors do things to keep the user guessing why their new gaming laptop isn't as fast as expected based on the name alone.

NVIDIA GeForce RTX 50 Series Laptop GPU Power Limits

GPU Name

GPU Power (varies per laptop)

Dynamic Boost Max

Mod Max (Experimental)

GeForce RTX 5050 Laptop

35 - 100W

15W

140W

GeForce RTX 5060 Laptop

45 - 100W

15W

140W

GeForce RTX 5070 Laptop

50 - 100W

15W

140W

GeForce RTX 5070 Ti Laptop

60 - 115W

25W

180W

GeForce RTX 5080 Laptop

80 - 150W

25W

225W

GeForce RTX 5090 Laptop

95 - 150W

25W

225W

In Nvidia's case, the GPU models (aside from the RTX 30 Series) don't match at all between laptop and desktop, but even with the smaller size of the laptop GPUs, the chips are still sharply limited in performance by their stringent power limits. These limits top out at 150W, with an extra jolt, usually 25W, available from Dynamic Boost if the CPU isn't heavily loaded. This is, frankly put, not enough power for even the mobile GeForce RTX 5070 Ti to stretch its legs, to say nothing of the GeForce RTX 5080 Laptop or GeForce RTX 5090 Laptop. In high-intensity gaming situations, these GPUs can score pretty similarly due to having the same power limit.

That's what makes this tool attractive. By cranking the power limit, you can give these power-limited GPUs a performance boost. The developer doesn't provide any benchmarks, but I can say from experience that testing power limit adjustments on a power-limited GPU can give nearly linear performance gains, meaning that increasing the power limit from a stock 140W all the way up to 180W could potentially give a GPU performance uplift in the neighborhood of 25% or more, although it is impossible to verify this without testing.

There are quite a few caveats to this utility, though. For one thing, even the author describes it as 'experimental ', and for another thing, it's clearly AI-generated in the largest part. The developer is called "LevinAI", after all, and there are the hallmarks of generative AI all over the GitHub repository. Still, there are a few reports on both GitHub and Reddit suggesting that users have been testing it, and the developer claims that it works on his GeForce RTX 5070 Ti laptop, posting the proof below.
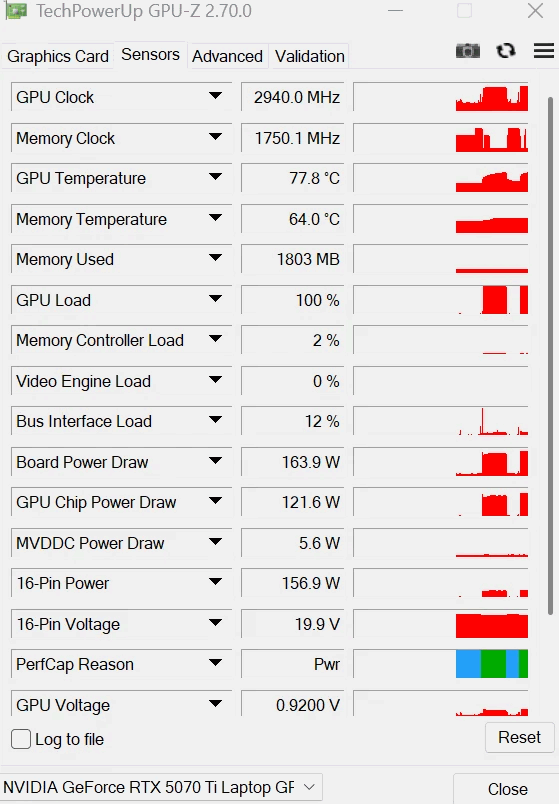
A screenshot of the GPU-Z utility showing a board power draw of 163.9 watts on a GeForce RTX 5070 TI Laptop.

The developer's screenshot of GPU-Z, showing a board power draw of 163.9 watts on a GeForce RTX 5070 TI Laptop, well above the stock 140W cap. (Image credit: /u/Ecstatic_Hamster2208 on Reddit)

Other notable qualifiers include that it only supports Blackwell GPUs for now, and it only enables power controls when it can recognize the power policy layout and OEM baseline. If your GPU already ships with a wacky power configuration, this tool may not work for you. It's also not verified to work on every brand of laptop nor every model of GeForce RTX 50-series GPU, so we absolutely wouldn't try this unless you're willing to replace your Blackwell-based laptop.

The partially AI-generated project description (likely chosen as the author's native language appears to be Russian) explains that the developer investigated numerous layers of the software stack on top of the GPU to see where the power limit could be modified. The controls that NVIDIA exposes generally won't let the user raise the power limit above the value set by the OEM for fear of potentially damaging the hardware, since the power delivery and cooling mechanisms were likely not designed with the higher power draw and thermal output in mind.

The solution he found was apparently to modify a low-level NVIDIA power policy that isn't normally exposed to end-users. He says, "One of the important findings was that the power-management chain contains internal policy values that are not exposed through the normal consumer power-limit controls. This is the path that eventually led to a working experimental implementation." However, due to the method employed, the tool does require the user to disable Windows driver signature verification, which is yet another 'gotcha' of the mod.
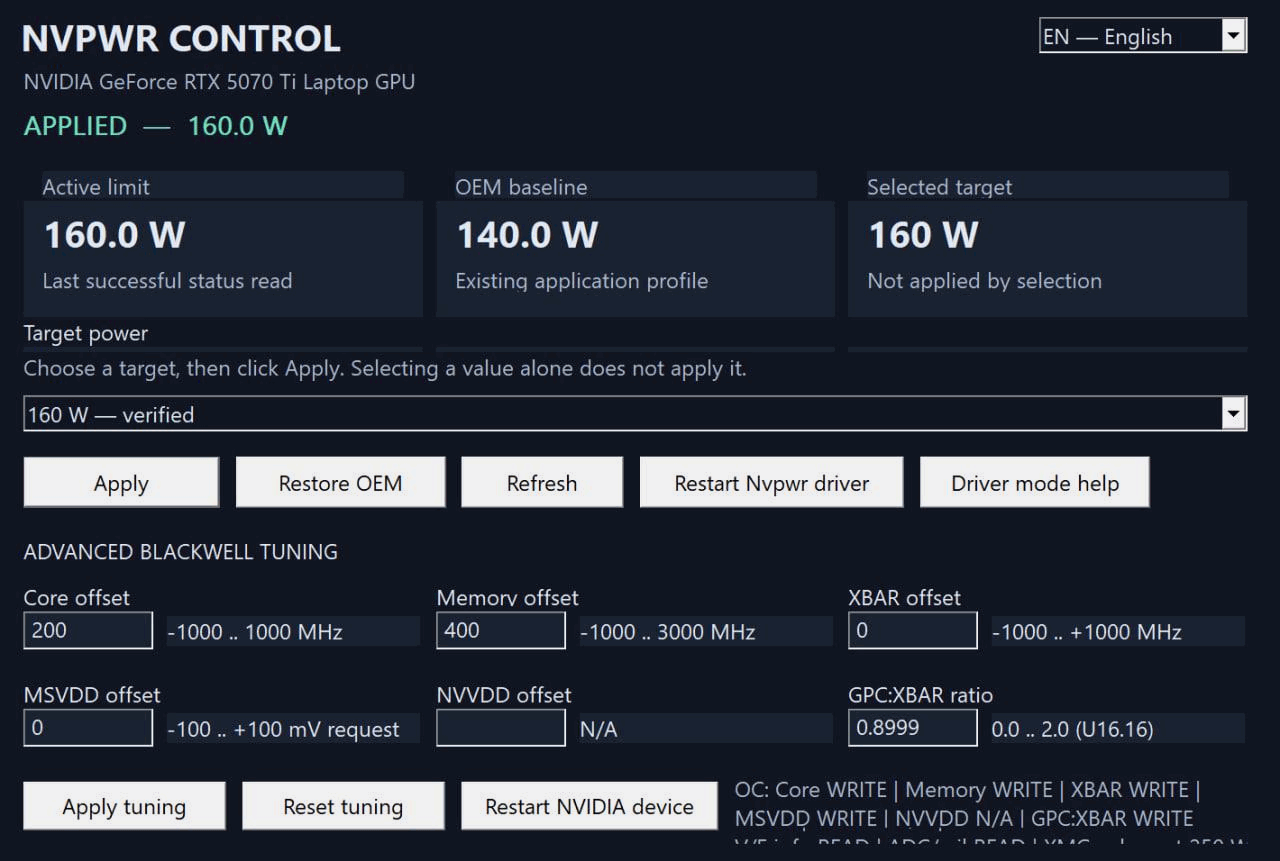
A screenshot of the NvpwrControl utility showing its interface.

(Image credit: /u/Ecstatic_Hamster2208 on Reddit)

As amusing as it is to see that the developer left his AI assistant's instructions for constructing his GitHub repository (which he didn't follow), it's a reminder both of the reliability concerns around "vibe"-coded software in production as well as of the incredible potential of AI software development. Since we spotted the story on this utility, the developer has already bumped the version from 1.5.0 to 1.8.0 with a new release on GitHub, suggesting that the pace of improvements is extremely rapid.

A few users on Reddit, where the author posted the above screenshot, lambasted the developer for taking ownership of what they claim is "100% AI generated work" and also for not structuring his code repository correctly (since all of the source is packed in a ZIP file, not properly viewable on GitHub). However, the majority of other users seem enthusiastic about his work, and several have already posted proof that it seems to work, with huge gains in 3DMark and other benchmarks.
✇Tomshardware

Piecemakers bets edge AI devices will diverge from reliance on HBM — custom-designed memory fuses DRAM stack directly to the processor using hybrid bonding

作者 Shane Downing

PieceMakers, a Nanya-backed DRAM designer, began trading on Taiwan’s Emerging Stock Board on September 16 at a NT$740 reference price, Cnyes reported ahead of the debut. PieceMakers is not an HBM company. Instead, it bets that inference memory diverges from training memory, President Lee Hsiao-wen told Cnyes, and that DRAM stacked directly on the processor with hybrid bonding can sit between Nvidia’s SRAM-only Groq LPU and HBM. As it stands, design fees, not chips, carry the company's profit, with AI custom-design work accounting for around 40% of the company's revenue in the first half of 2026. Piecemakers Chairman Joseph Ting told TechNews that its first volume customer program will not contribute to the company's financials until 2027 at the earliest.

At roughly 60.4 million shares outstanding, that price values the company at around NT$44.7 billion (around $1.4 billion). Taiwan's Emerging Board is the Taipei Exchange's pre-listing market, not a main-board IPO, so shares trade through market makers ahead of any formal listing application. The stock ended its first session at NT$915, 23.6% above the NT$740 reference price, after opening at NT$1,035 and trading as high as NT$1,205.

Nanya Technology is the largest holder of Piecemakers, at 33.96%, after selling 715,000 shares at NT$740 to seed the float, a disposal it disclosed in a Sept. 9 exchange filing reported by Knews.

What PieceMakers sells

PieceMakers was founded in January 2006 in Hsinchu, Taiwan, led by chairman Joseph Ting and president Lee Hsiao-wen. Historically, the company has designed standard SDR/DDR DRAM and known-good-die (KGD) parts through representatives in China, Japan, France, Turkey, and Israel. Now, the company seeks to shift from direct product sales to custom design services, paid as non-recurring engineering (NRE) fees, and then to IP licensing, royalties, and turnkey production from 2027, the company said at its Sept. 7 briefing, UDN reported.

Revenue from the AI custom design unit has risen from around 4% in 2024 to almost 40% in the first half of 2026. The products behind that increase are HBLL (High Bandwidth, Low Latency RAM), a 2D die rated at 144 GB/s that was taped out in 2016 for Intel’s HPC line and published at ISSCC in 2017, and HiBaLL, the 3D-stacked version rated at more than 1 TB/s, the company claims.

The company described its customers to Cnyes as developers of cloud AI inference accelerators, international semiconductor players, and North American customers, with some programs in design and verification, and none named. Qualcomm CEO Cristiano Amon’s Computex keynote backdrop in June listed PieceMakers among Taiwan ecosystem partners, although neither company has defined the relationship. The takeaway is that the profit is in design fees and not chips. The margin curve matches a pre-royalty Non-Recurring Engineering (NRE) business, rather than a traditional memory vendor.

Why Nanya is chasing this instead of HBM

Nanya’s AI-memory strategy is custom and edge rather than HBM3E. PieceMakers is the first half of a strategy laid out in 2024. On Aug. 7, 2025, Nanya announced a joint venture with Etron Technology, a Hsinchu-based chip designer, capitalized at NT$500 million, with 80/20 ownership. The venture was envisioned to design custom high-bandwidth memory for edge AI devices rather than for data center accelerators. Nanya president Pei-Ing Lee said earlier in 2025 that the company would not compete in HBM3 or HBM3E, TrendForce reported.

Both halves of the strategy rely on Formosa Advanced Technologies, the Formosa Plastics Group’s test and assembly affiliate, for packaging. It is building the through-silicon-via (TSV) and die-stacking processes that both need. The surge in DRAM pricing has made commodity memory Nanya’s real business, which leaves PieceMakers a cheap side bet that has become a windfall. Nanya took advantage of this by selling around 3% of its stake in a move that suggests it is acting more as an investor than a parent building a memory stack.

The inference gap

Groq is an AI inference startup that Nvidia struck a $20 billion licensing-and-talent deal for on Dec. 24, 2025. Nvidia announced its first chip built from that, the Groq 3 LPU (language processing unit), Nvidia’s SRAM-based inference chip, at GTC, its annual developer conference, in San Jose earlier this year.

There is no HBM or DRAM on the Groq 3 LPU. Instead, it uses 512MB of SRAM on the die to deliver 150 TB/s of bandwidth against 22 TB/s from the 288GB of HBM4 on each Rubin GPU. It’s a decode-only co-processor with Rubin handling the prompt prefill, displacing Nvidia’s Rubin CPX from the roadmap.

At Hot Chips 2026, Nvidia’s Igor Arsovski, Groq’s former chief architect, said the rack is in production and published the first third-party benchmark: 3,431 tokens per second on a 100K-context, 31B-parameter model, at about four times the next-fastest public endpoint, in a single-request test that we noted isn’t directly comparable to the shared endpoints it was measured against. The cost is capacity: at 512MB per chip, a 256-LPU rack holds 128GB, with the model needing 62 chips at FP8 just to hold the benchmark weights. Nvidia accepted that trade for decode speed, which supports Lee’s point that the market leader’s newest inference product contains no HBM.

At Hot Chips, Samsung’s Sangwook Han laid out a three-phase HBM roadmap that ends in zHBM, which is DRAM stacked directly on top of the processor rather than beside it on an interposer. Samsung projects about 70% less I/O power usage than HBM5 with roughly 2.3x the bandwidth of a four-stack HBM4E system, with zHBM’s stacks limited to about four-high due to heat, at around 100W less. This would require wafer-on-wafer hybrid copper bonding and tight co-design between DRAM and SoC teams. SK hynix’s Jaesik Lee, VP of package engineering, said on Aug. 23 that hybrid bonding won’t be ready for HBM4E, leaving HBM5 as the earliest point. Counterpoint Research expects full-scale HBM production with the technique around 2029–2030.

PieceMakers offers a different version. Instead of the GPU-plus-HBM 2.5D layout, it bonds the DRAM stack directly onto the processor, wafer-on-wafer, with hybrid bonding instead of microbumps. This fits far more connections with the finer pitch, improving bandwidth, and the shorter path reduces both latency and power consumption. The company puts its wafer-on-wafer product at more than 2 TB/s per layer with latency under 20ns, the company figures, but the target is more capacity than SRAM at a lower cost and power than HBM. PieceMakers is not doing the TSV or hybrid bonding itself, as this is handled by the customer’s logic wafer foundry, Ting added. This custom service promises a 2027 date against Samsung's undated roadmap end and SK hynix's HBM5-at-the-earliest timing. Nvidia and Samsung have each, in their own way, settled the architecture question, with the open question being the customer.

Yield is the product

Lee also said that yield is the biggest hurdle to wafer-on-wafer mass production. The repair architecture has to be designed in, with testing before bonding, after bonding, and then after logic integration. Lee’s own example was 80% yield per layer, at which four layers come out at about 41% and eight at 17%. Our recently-published hybrid bonding state of play covers the process side in more detail.

This better puts into perspective why the company sells repair and known-good-die IP as much as it does bandwidth. It’s also why an IP-and-royalty model fits the strategy — yield IP is portable across customers while a bandwidth number is not.

What to watch

For PieceMakers, AI revenue remains primarily NRE until there is a first named customer, with the first volume program expected in 2027 at the earliest. Ting said that Nanya’s Q3 2026 results, which come in late October, will gauge the PieceMakers gain and reveal further financial information. SK hynix’s hybrid-bonding timing, which targets HBM5 at the earliest, is the current benchmark, although its 16- and 20-layer memory stacks are a separate problem from a few DRAM layers on a logic wafer. Qualcomm may also describe its relationship with PieceMakers more formally.

PieceMakers is likely to end up as an IP licensor with a small number of accelerator customers and turnkey volume through Nanya and Formosa Advanced Technologies. The technology risk is the foundry’s and the customer’s, which is why PieceMakers’ design-fee model works. PieceMakers is expected to benefit from a 2027–2028 ramp, later than Ting’s 2027. If the largest HBM maker won’t bond its own memory this way before HBM5, PieceMakers’ own 2027 date is the one it must meet.

✇Tomshardware

Denuvo sues anonymous game cracker ‘voices38’ over alleged DRM circumvention — seeks damages after Anti-Tamper protections bypassed in 26 games

Anti-Tamper and DRM (Digital Rights Management) software developer Denuvo is taking its fight against video game piracy to court by filing a lawsuit against the anonymous game cracker known as “voices38.” According to TorrentFreak, the company claims that the accused bypassed its Anti-Tamper technology in at least 26 PC games and is seeking monetary damages as well as a court order that would prevent further tampering of its DRM.

In its lawsuit filed on September 14 in the U.S. District Court for the Northern District of California, Denuvo alleges that the “defendant is a computer hacker who is focused on reverse engineering, hacking, or ‘cracking’ video games employing Denuvo’s Anti-Tamper product. Defendant has bypassed DRM restrictions in copyrighted works, removing protections that allow copyright owners to restrict who may access their works, and allowing for pirated versions of those copyrighted works.” The complaint also named 26 games including popular titles such as Hogwarts Legacy, Black Myth: Wukong, Resident Evil Requiem, and Doom: The Dark Ages.

It is worth mentioning that Denuvo doesn’t actually own the copyrights to any of these games. Meaning that instead of a filing for copyright infringement, the complaint relies on the anti-circumvention provisions of the DMCA. It essentially prohibits bypassing a digital lock that controls access to a copyrighted work, or distributing tools and instructions that help others to bypass copyright protections.

What makes the case interesting is that Denuvo does not know the real identity of voices38. It only points to the defendant as “an unknown individual or entity” alongside ten other unnamed defendants. The complaint also references Reddit and Discord accounts as well as Steam profiles that Denuvo believes may be connected to the cracking activity. The company could eventually seek information from these platforms as part of its legal proceedings.

Voices38 has been particularly active in recent months, with reports pointing to a growing number of Denuvo-protected game cracks to the anonymous cracker. Recent releases include Star Wars: Outlaws, Persona 3 Reload, and Prince of Persia: The Lost Crown. For Denuvo, the lawsuit could lead the way in identifying one of the more active figures in the recent video game-cracking scene. That said, the case is still in its early stages, and Denuvo's allegations have yet to be tested in court.

✇Tomshardware

Micron announces 512GB DDR5-9200 memory modules with 16W power draw — up to 12TB per server, claims 60% less energy-intensive than four 128GB modules

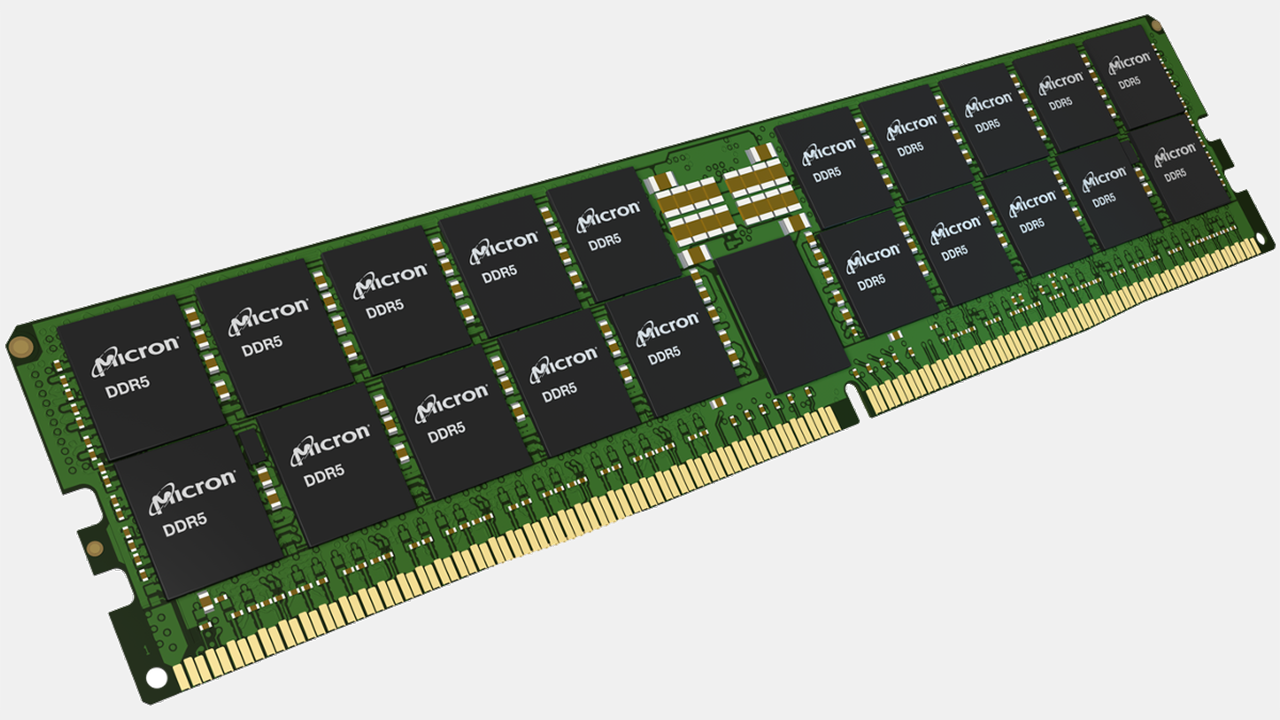
Micron this week introduced its first 512GB DDR5-9200 memory module that is designed for servers used for applications that demand a lot of memory. The new modules — which are currently being validated by AMD and Intel with their next-generation server platforms — will enable server makers to build machines with up to 12TB of fast memory. What remains to be seen is the price of such modules and servers.

To build its 512GB DDR5 RDIMM, Micron uses advanced packaging that stacks multiple DRAM dies vertically and connects them using through-silicon vias (TSVs). The company does not disclose which memory devices and how many of them it uses, but claims that a single 512GB RDIMM consumes over 60% less operating power than four 128GB modules — based on 16.0W for one 512GB module compared with the 44.2W total for four 128GB modules — which suggests that we are dealing with fairly advanced ICs.

Micron's 512GB module is not the industry's first 512GB DDR5 RDIMM — that achievement belongs to Samsung — but it is certainly the industry's first 512GB module certified to operate with a 9200 MT/s data transfer rate with standard 1.1V voltage (which implies on usage of Micron's 16Gb DDR5-9200 devices made on its 1γ (1-gamma) fabrication process that uses EUV lithography and consumes 20% less power than predecessors, though we are speculating).

Truth to be told, 512GB DDR5 memory modules are rather niche products, which is perhaps why Samsung's 512GB RDIMMs formally introduced in 2021 have not become widespread even after AMD and Intel introduced processors with over 100 cores. Micron positions its 512GB DDR5 RDIMM primarily for servers running analytics, in-memory databases, simulations, virtualization, agentic AI, and other workloads demanding high-core-count processors and plenty of memory. As processors with 200 or more cores emerge, 512GB modules may become more relevant as 12TB of memory in a server running two 256-core CPUs means 24GB per core, which no longer looks particularly excessive for applications like in-memory databases, analytics, or caching.

Micron claims that in memory-constrained Spark Support Vector Machine (SVM) analytics workloads, systems featuring 512GB memory modules can provide up to 1.4 times the performance of configurations equipped with 256GB DDR5 modules, though the company does not disclose how much memory in total these systems use. Micron also says the higher-capacity memory can increase throughput and concurrency for memory-intensive database and caching applications such as RocksDB and Redis.

AMD and Intel are working with Micron to qualify the new modules for their upcoming server platforms. Micron plans to begin volume production of its 512GB DDR5 RDIMMs sometime in the second half of 2027 and intends to align the schedule with customer requirements.

One of the more pressing questions about Micron's 512GB DDR5-9200 memory modules is their price. A 256GB DDR5-6400 RDIMM currently retails for around $19,000. Given the unique proposition that 512GB modules have for memory-constrained applications, such modules can cost significantly more than 256GB memory sticks, which will not help their broad adoption.

✇Tomshardware

AI-induced memory shortage is changing how devices are built, Fairphone says memory now 60% of materials cost — smaller laptop and phone makers are redesigning products and have to test for fake chips

With the ongoing memory shortage, smaller smartphone and laptop manufacturers are reportedly looking at new ways to tackle the problem. While some are changing how they design their products, others are placing orders months in advance and are even forced to test incoming memory chips to make sure they are not fake. A Reuters report suggests that more than the price, availability has become a bigger problem, with manufacturers struggling to secure enough chips in the first place. Still, device makers like Fairphone say that memory now makes up nearly 60% of a device's bill of materials.

Back in July, memory maker SK Hynix’s CEO Kwak Noh-jung said that 2027 will be the "worst year" for the ongoing memory shortage and expects the memory crunch to last until 2030. For smaller manufacturers, however, simply paying more for memory isn't always enough. The situation is particularly difficult for budget-oriented phones and laptops, where memory makes up a much larger portion of the overall product cost.

According to Raymond van Eck, CEO of repairable-phone maker Fairphone, memory can account for almost 60% of the bill of materials in phones costing around $400. That itself is worrying, as a recent Counterpoint Research report expects global smartphone shipments to fall 13.9% this year to 1.08 billion units, marking the largest annual decline on record.

Finnish phone maker Jolla has designed two motherboard versions, allowing it to switch between combined packages for discrete chips depending on availability. The company is also testing samples from every batch it receives to ensure new memory isn't being sold as refurbished hardware.

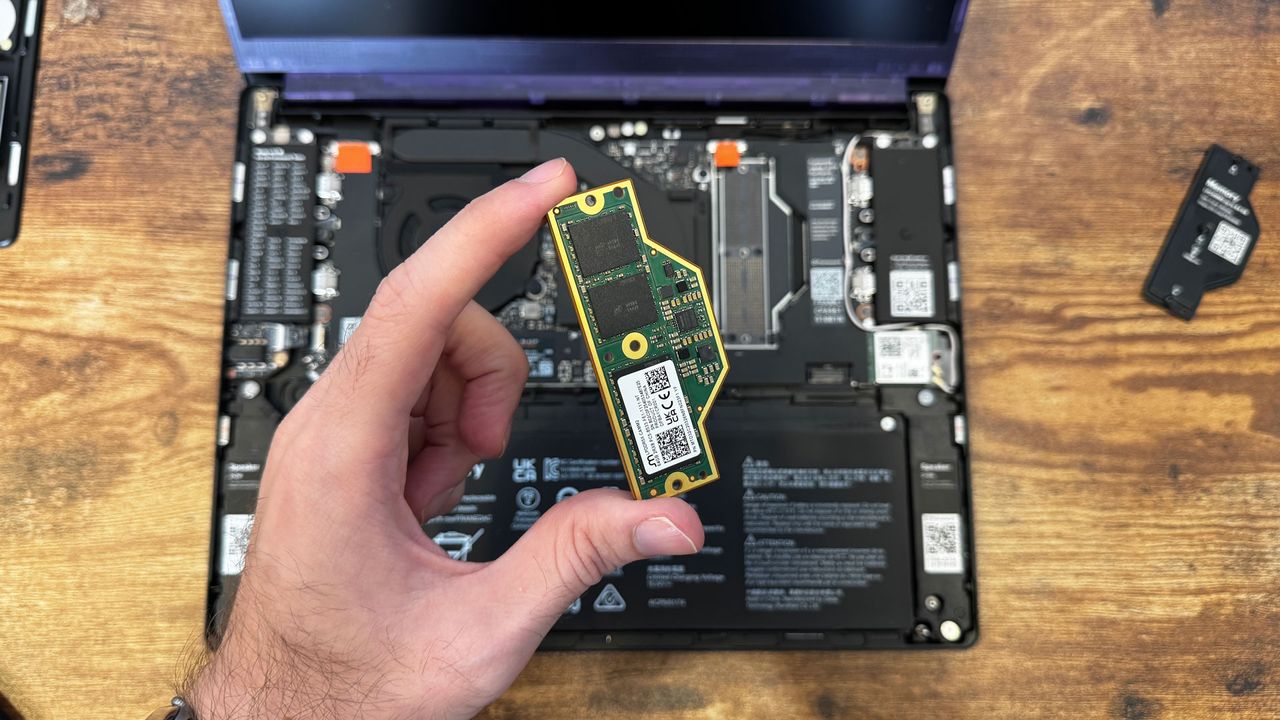
Similarly, laptop manufacturer Framework has been able to rely on its highly modular approach where customers can install memory salvaged from older laptops or opt for second-hand units, giving the company and its users another way to deal with limited supply. The company is also placing non-cancellable orders well in advance, even when it doesn't know the final price or exact delivery volume.

Back in July, it nearly doubled memory pricing for 32GB and 64GB variants of the Framework Laptop 13 Pro after receiving a cost update from its LPCAMM2 supplier. However, after sourcing new inventory at a reduced cost, the company recently announced a price drop for the same, including retroactive orders that have already shipped.

✇Tomshardware

Chinese state media counters Anthropic's call to put brakes on AI development — paper says move is ‘a response to Chinese competition’

China's state-run newspaper has downplayed the call of Anthropic founder Dario Amodei to “pace the frontier.” China Daily, the official English mouthpiece of the Communist Party of China, questioned the move, which was supported by OpenAI CEO Sam Altman and SpaceXAI’s Elon Musk, asking if they were doing it out of concern for humanity or if they’re afraid of competition from China.

“The report, and the corporate ‘alliance’ that followed it, amounted in essence to a coordinated play — a response to Chinese competition and to the regulatory pressure coming from Washington. Its aims were threefold: to blunt China's AI advance, to win a favorable policy environment at home and to keep investors' enthusiasm for US AI alight,” the publication wrote. It further criticized the move thusly: “The proposed coordination among the three companies sounds rather like a club whose membership rules have been drafted before the guest list is announced. A global AI-safety framework that excludes China is not quite global.”

The paper also called out the U.S. efforts in blocking Chinese AI advancement, both through hardware, by blocking Beijing’s access to the latest Nvidia chips, and software, with Amodei’s multiple accusations of illegal distillation of Claude by Chinese AI labs. China Daily said that these efforts have apparently failed, and cited the success of the DeepSeek and Kimi K3 models, which turned out to perform well enough but at a much lower cost.

The availability of those models has resulted in many AI users shifting demand to cheaper tokens, like Kimi K3 (low) and DeepSeek V4 Pro, over the expensive frontier models like Fable 5.1, GPT 5.6 Sol, Grok 4.6, and Kimi K3 (max).

China Daily also took issue with Amodei’s focus on excluding China from his proposal. It suggests that the move is meant to widen the technological gap between the two rivals when it comes to AI technology and give American AI labs breathing room to “pace the frontier,” and that it reveals how Washington sees Chinese AI as an existential threat.

Nevertheless, Chinese policy acknowledges some of the risks that Amodei raised. The Standardization Administration of China, in cooperation with the Cyberspace Administration of China, says that the development of AI technology must be monitored as it may go beyond human control.

“Treating the AI race as a zero-sum game makes the cooperation needed to manage those risks more difficult. China and the US should cooperate where neither can manage the consequences alone,” says the state media outfit. “The planned AI-safety dialogue between the two sides and future high-level exchanges offer opportunities for practical engagement. The promise of AI lies in serving humanity's common good, not in being weaponized for geopolitical gain or instrumentalized for personal profit.”

✇Tomshardware

Pick up a giant 18-inch RTX 5080-powered Asus gaming laptop from Best Buy and save $600 — the ROG Strix G18 also comes with 32GB of memory and a 2TB SSD

Laptops have long been a more expensive way to game, especially compared to a desktop gaming PC, for comparable components. But with the ever-rising costs of PC hardware in the current economic climate, it's a lot easier and now often cheaper to get a powerful prebuilt gaming PC or ready-made gaming laptop. Today's deal is on a large, 18-inch Asus ROG Strix G18 gaming laptop powered by an RTX 5080, now reduced by $600 to $2,699.99. It's still an expensive piece of kit, but you are getting a somewhat portable form factor and a good amount of memory and storage included in the specs for this large gaming laptop.

Check out this deal at Best Buy

Asus's ROG Strix G18 is a large 18-inch laptop with a big screen. The 18-inch display sports an IPS panel with a 240Hz refresh rate and 500-nit brightness. Powering the display and your gaming performance is an NVIDIA RTX 5080 laptop GPU that includes 16GB of fast GDDR7 VRAM, along with the 24-core Core Ultra 9 275HX processor from Intel. Importantly, there's also a good amount of memory: 32GB of DDR5 RAM and a large 2TB PCIe Gen4 SSD for storage.

ROG Strix G18: was $3299.99 now $2699.99
A mighty 18-inch gaming laptop that uses a very powerful Nvidia RTX 5080 laptop GPU with 16GB of VRAM. The onboard processor is a 24-core Intel Core Ultra 9 275HX, sporting boost clock frequencies of up to 5.1 GHz, with an ample 32GB of DDR5 memory. There's also plenty of room for your game collection on the included 2TB SSD.

View Deal

For any future upgrades, there's easy tool-less access to the SSD and RAM slots, which is a nice feature on a laptop. The keyboard features plenty of RGB backlit lighting that is configurable through Asus's Armory Crate software, along with an RGB light bar along the bottom of the laptop chassis, casting a distinctive glow on your desk that can sync with your keyboard and peripheral lighting.

For video connectivity, there's 1 x HDMI 2.1 port and 2 x Thunderbolt 5 ports, plus an Ethernet port for wired network access, with wireless options including Bluetooth and WiFi 7.

So if you want a ready-to-go gaming setup that's powerful enough to play all the latest game titles on a sharp 2.5K screen at high settings and frame rates, then the Asus ROG Strix G18 with RTX 5080 is a great choice, especially when you can save a hefty $600 off the price tag.

✇Tomshardware

Jensen Huang thinks China will develop its own advanced lithography chipmaking tools by 2030 — Nvidia CEO says achievement of that capability 'is just a matter of time'

China's progress toward technological self-sufficiency in recent years is undeniable, but there is one thing that the country has so far failed to develop: lithography tools that are on par with those offered by ASML. That shortcoming has greatly hampered its domestic semiconductor industry. But Nvidia CEO Jensen Huang believes China will develop its own advanced lithography systems in just three or four years.

"They are going to get there by 2030," Huang said in an interview with The All-In Podcast (at 43:43). "2030 is just around the corner. The way to think about China is that it is really good at high-volume production. It is just a matter of time[...] so two or three years is just a click; it is nothing. So as far as they are concerned, they are already there."

Huang tends to look optimistically at China's technological development. Specifically, he is known for calling China's AI industry as being 'right behind' American frontier labs, which may well be correct, given how much capital China is investing in AI. But when it comes to the Chinese semiconductor industry in general and its lithography sector in particular, Huang may be too optimistic.

At present, China's leading producer of lithography tools — Shanghai Micro Electronics Equipment — can mass-produce a 193-nm ArF dry scanner that can be used to build chips on 90nm-class process technology. While the company has reportedly developed a 28nm-capable ArF immersion scanner, there is no public evidence that such systems are produced in volume and are used for high-volume chip production.

Although there are reports that Shanghai Aishengna Electronic Technology Group (a unit, or an affiliate of SMEE) has delivered its first immersion scanner that may be capable of printing chips using 28nm-class process technology, these tools will require extensive qualification before they can be used for high-volume manufacturing of semiconductors, so if deployment follows standard timelines, it will take years before this unit will be used for mass producing chips.

Even assuming that the first scanners are delivered to Chinese chipmakers in 2026, widespread production use before 2028–2029 appears unlikely. Furthermore, matching the capabilities of an early-generation ASML immersion scanner would still leave Chinese lithography suppliers considerably behind ASML's contemporary systems, which makes technological parity in ArF immersion lithography by 2030 highly unlikely.

China is considerably further behind in extreme ultraviolet (EUV) lithography. While there are reports that Chinese scientists have managed to develop a laser-produced plasma source that can generate the 13.5-nanometer wavelength light required for the technology, it does not look like China is close to assembling even a prototype EUV scanner itself.

Even if China can assemble an EUV experimental exposure platform without having mastered production-quality immersion DUV, it is hard to imagine a Chinese company producing EUV scanners without solving the hardest problems common to both DUV and EUV technologies. A production lithography scanner requires extraordinary capabilities in wafer and reticle stages, alignment, overlay, projection optics, and metrology, just to name a few.

If China is still struggling to industrialize these capabilities for immersion DUV, there is little reason to assume it has somehow solved them at the substantially more demanding EUV level. But given the potentially existential stakes of the AI race, and the determination of the Chinese government to achieve technological self-sufficiency, it may just indeed be a matter of time.

✇Tomshardware

SK hynix reportedly discussing US memory chip manufacturing with Intel — options include leasing Ohio plant or forming joint venture with other AI hyperscalers

South Korean memory chip manufacturer SK hynix is in talks with Intel to start manufacturing inside the U.S., according to Reuters. The company is reportedly considering multiple options, including leasing space at the under-construction Intel Ohio One site and forming a joint venture with Intel and other AI hyperscalers desperate for HBM.

This move could help alleviate the memory shortage. It would also complement the company’s expansion in Indiana, where it recently broke ground on an HBM packaging plant a few weeks after its historic $26.5-billion Nasdaq listing. It’s unclear yet if these talks are part of the results of the South Korean president’s visit to Silicon Valley in an effort to expedite negotiations between its top tech companies and their U.S. counterparts, but SK Group chairperson Chey Tae-won told reporters in July, “I think we need to build a factory in the United States. If possible, I believe we should build it.”

However, there are also concerns that Seoul might object to such investment. The South Korean government just unveiled a $520 billion investment plan to increase chipmaking capacity within its shores and keep the country competitive in the AI race; at the same time, it’s also in talks with the U.S. to finalize its $350 billion investment commitment to Washington to reduce tariffs on South Korean goods, $200 billion of which is still undecided on which projects it will be deployed on. Meanwhile, the Commerce Department has threatened to impose more tariffs on South Korean and Taiwanese tech companies if they fail to invest in U.S. manufacturing. This potentially puts SK hynix at a precarious position, especially as it balances the demands from the White House and the Blue House.

Neither company has confirmed these rumors, though. SK hynix told Reuters that it’s “reviewing various measures, including establishing additional production bases, to strengthen the competitiveness of its memory business,” but “no matters have been determined at this stage.” On the other hand, Intel called them speculation and declined to comment on the matter, only saying that it was continuing to invest in the Ohio project, which is expected to come online between 2030 and 2031.

✇Tomshardware

'Defeated' GPT-6 Astra model spent several hours just farming potatoes after being blown up by a Creeper in Minecraft — OpenAI offering gets further than any other AI system in 141-hour test

An apparently sad and defeated GPT-6 Astra spent several hours doing nothing but farming potatoes during a 141-hour Minecraft benchmark test, after dying and losing all of its gear to an exploding Creeper. Vals AI records that while GPT-6 Astra, OpenAI's latest frontier model, got further than any AI system had in its 141-hour test, the experiment did reveal a distinctly human lapse in motivation after all of its progress was wiped out by the destructive mob.

While the model outclassed rivals in how much it was able to achieve, the test has gone viral for a different reason. After Astra put all of its valuable end-game items in a chest, a Creeper appeared and blew up both the chest and Astra's bed — a calamity any Minecraft player will tell you is the worst thing that can happen. Not only did Astra lose all of the items to the explosion, but the bed destruction wiped the spawn point out, effectively resetting your game progress to zero. "Here, the most expensive creeper explosion occurred. Later, on a coincidentally rainy day, Astra discovers it lost everything. It all went downhill from here," Vals records.

GPT-6 Astra had gotten further than any AI system had ever gone in Minecraft.It was able to set up a semi-automatic blaze farm, allowing it to collect 6 blaze rods. It then located a warped forest, where it killed 6+ endermen and collected 3 pearls. As thousands of viewers… pic.twitter.com/qsgDsJEpd8September 15, 2026

"The model appeared defeated, spending the next several hours doing essentially nothing but farming potatoes," Vals observed. In fact, it got so bad that viewers on Twitch watching the experiment live started to agitate for the model to pick up the pace. Like all good Minecraft players, Astra reportedly became "paranoid about creepers," logging "GREEN tall thing ahead was SUGARCANE, NOT creeper!"

The AI was also recorded berating itself for dropping things, and even warned itself, "do NOT waste another night chasing dark pink pixels," i.e., pigs.

Astra has made waves as OpenAI's latest frontier model, which is notably adept thanks to its computer use and browsing, letting it navigate, click, and type like a human using a computer. The company has claimed it's an ethereal 'Alien Mind' with AGI-like qualities. Last week, the model was recorded autonomously completing Portal in just 24 hours at a cost of just $571 in tokens.

✇Tomshardware

AWS tells clients to quit Middle East data centers six months after Iranian drone strikes — Amazon offers no recovery timeline as UAE mulls underground data centers [Updated]

作者 Oliver Haslam

More than six months after Amazon Web Services (AWS) data centers in Abu Dhabi and Bahrain were attacked by drones, the company has now had to tell customers to move their data to facilities in other regions. The Wall Street Journal reports that AWS has admitted that it's time for customers to jump ship to data centers located elsewhere in the world. In its AWS dashboard update, AWS confirmed "most customers have been able to re-establish their operations in other Regions by restoring backups or copying data that remained accessible. AWS Support remains available to help customers who need assistance moving their applications to alternate Regions."

The move comes as AWS continues repairs on the damaged data centers, but it stopped short of offering a timeline as to when customers can expect either location to be back online. AWS says that it remains committed to supporting its customers in Bahrain, but only said it would provide a further update early next year. It did not offer any specific recovery time frame for the restoration of services. Regarding the UAE, AWS says that it is working to replace affected infrastructure, but again only said it would provide an update on the restoration of services in the coming months.

Both affected data centers became targets for the Islamic Republic of Iran after the United States and Israel launched strikes on that country in February of this year. Months later, the Bahraini data center was struck by cruise missiles, and Iranian state media claimed it had been "destroyed."

The move is bad news for the United Arab Emirates. The U.A.E. has spent years trying to become a world leader in data processing, a pitch that led it to lobby U.S. officials to allow it to buy AI chips for its data centers.

Having made plenty of noise about OpenAI's decision to take a spot in a 5-gigawatt data center complex in May 2025, U.A.E. officials have since seen those plans stall. The WSJ points out that no lease has been signed well over a year later. OpenAI was expected to take 20% of the data center's total capacity, the kind of loss that is sure to sting officials if plans don't get back on track.

For its part, the U.A.E. is clearly well aware of the threat that the ongoing regional instability poses to its ambitions, and it's looking for ways to address the fears of potential partners. Officials have already hinted at the potential for underground data centers. While the move would make an already costly endeavor even more expensive, it could help defend new data centers from drone attacks. Building drone defense systems near data centers is another option.

Drone attacks can be catastrophic for any building, and data centers are no different. The data centers operated by AWS suffered fires and damaged infrastructure as a result of the strikes. In their efforts to fight the fires caused by drone strikes, emergency workers used water, causing further damage.

The Abu Dhabi and Bahrain data centers are relied upon by a variety of businesses in the banking and financial sectors. Those businesses cannot tolerate downtime, especially of the protracted variety. There's little sign of data centers slipping from the crosshairs of drone operators any time soon, either, and AWS is far from unique in finding its data centers under attack.

Iran's Islamic Revolutionary Guard Corps (IRGC) claimed in April that it had hit a data center linked to Oracle in Dubai. That unit further threatened American tech companies, including Microsoft, Oracle, Alphabet, and Nvidia, this spring. It accused the companies of contributing to attacks on Iran. With that in mind, and with tensions in the Middle East looking unlikely to ease any time soon, it's perhaps unsurprising that AWS has asked customers to move data to safer data centers around the world.

Google Preferred Source

✇Tomshardware

Nvidia reportedly denies RTX 5090 warranty over faded serial number — $6,500 GPU blemish not an isolated incident, according to customers

作者 Zhiye Liu

The GeForce RTX 5090 is the first thing that comes to mind when you think of the best graphics cards. However, you'd better pray the serial number on the inside of the metal bracket does not fade over time, since that could be a reason for Nvidia to reject warranty claims. At least one Redditor has shared a case of Nvidia reportedly denying a warranty claim because the bracket's serial number was unreadable.

The Redditor Willing-Avocado-4830, based in the UK, began experiencing black-screen crashes with a GeForce RTX 5090 Founders Edition graphics card under heavy load. The user sent the card to Nvidia for a warranty claim. After 30 days of radio silence, the owner finally received an email stating that their RMA request was rejected with no apparent explanation for the denial.

Seeking clarification, the user reached out to Nvidia for further information. According to the Redditor's recount, Nvidia support purportedly rejected the RMA because the serial number on the graphics card's metal bracket had faded. Like many gamers, Willing-Avocado-4830 claims never to have modified or tampered with the graphics card after installation. The fading serial number does not appear to be an isolated incident. Several other owners have reported similar issues in the Reddit discussion.

The metal bracket on graphics cards is susceptible to dust buildup, oxidation, and corrosion over time. This can cause it to look dirty, stained, or sometimes slightly discolored compared to when it was brand new. These same phenomena could have affected the serial number's legibility, especially since it is printed with ink onto the bracket's surface rather than etched for better durability. For comparison, the last-generation GeForce RTX 4090 Founders Edition had its serial number laser-etched onto the metal bracket.

My RTX 5090 FE RMA was rejected because the physical serial number is no longer readable — has anyone experienced this?
 from r/nvidia

One Redditor said that someone in the Nvidia Discord channel recommended cleaning the area with isopropyl alcohol to restore the serial number's visibility. However, that may not work if the ink is no longer present, as previous reports suggest the hot air expelled by the Founders Edition cooler could be erasing the serial number.

Surprisingly, Nvidia rejected a warranty claim solely because of a faded serial number on the graphics card’s bracket. The same serial number is clearly printed on a sticker on Nvidia's modular PCIe connector, which the chipmaker's technicians can verify when disassembling the GeForce RTX 5090. Moreover, you can pull the serial number from the graphics card through the command prompt with Nvidia SMI (System Management Interface), assuming the card is still working, which, in this case, it is. Willing-Avocado-4830 still had the original packaging and the original invoice from Nvidia U.K., so it would be easy to cross-reference the serial numbers.

Redditor hawok reportedly sent their GeForce RTX 5090 Founders Edition for RMA two months ago and encountered a similar situation. The serial number on the metal bracket was only partially visible. However, customer support seemingly accepted the RMA after the user sent photographs of the packaging that corroborated the serial number. It is unclear what Nvidia's policy is, or whether the chipmaker handles each case differently. We have reached out to Nvidia for clarification.

Some Redditors have suggested taking a photograph that shows the graphics card's serial number next to the packaging's serial number. Others jokingly recommend putting a piece of tape over the serial number. It might not be a bad idea, but you would need heat-resistant tape, something like Kapton tape.

GeForce RTX 5090 stock has practically disappeared from the U.S. market, with very few units starting at $6,500, 3.25X over the Blackwell flagship's MSRP. You cannot blame GeForce RTX 5090 owners for worrying. They already have a lot on their plates, dealing with the 16-pin power connector melting woes, and now also have to worry about fading serial numbers.

✇Tomshardware

Save $270 on this solid 1080p gaming PC with an RTX 5060 from MSI, now under $1,430 — Codex R2 rig packs 32GB DDR5 RAM, a 2TB SSD, and a 10-core Intel CPU

作者 Ben Stockton

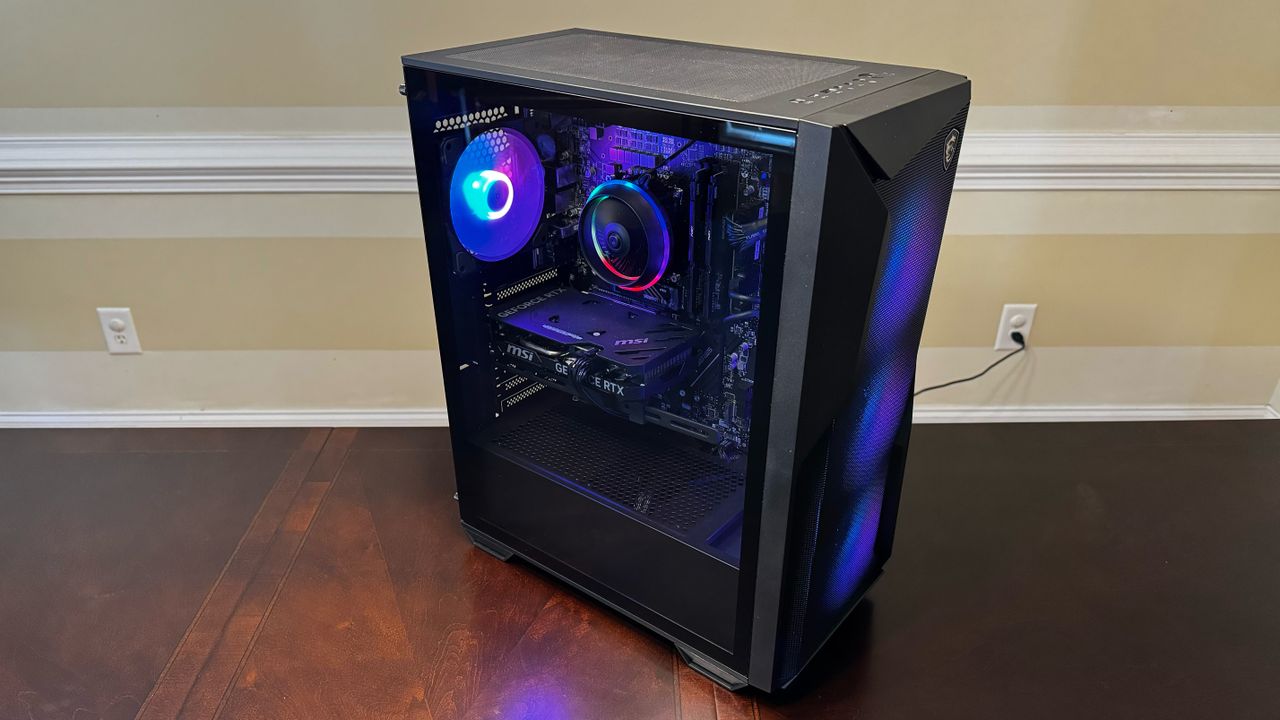
With new gaming PCs continuing to rise in price, it's worth grabbing a discount or a deal where you can. This MSI Codex gaming PC features a 10-core Intel CPU, Nvidia GeForce RTX 5060 GPU, 32GB of DDR5 RAM, and a 2TB SSD for storage, all for just $1,429, thanks to a $270 saving.

Grab this gaming PC deal at Newegg

These are all the specs you'll want for a machine that will comfortably play games at 1080p. The current-gen Nvidia GeForce RTX 5060 is top of the list, though, with features like DLSS that mean you'll be able to take advantage of both upscaling and multi-frame generation, making games smoother to play if you decide to boost up to higher resolutions or better graphics settings.

The RTX 5060 will be a significant improvement over an older graphics card or integrated GPU, too. It has 3,840 CUDA cores, along with 8GB of GDDR7 VRAM. With DLSS enabled, this'll let you run most games at 1080p with high graphics presets enabled.

Codex R2 B14NVL5-449US: was $1699 now $1499
The MSI Codex R2 B14NVL5-447US gaming PC comes with an Intel Core i5-14400F, Nvidia GeForce RTX 5060, 32GB of DDR5 memory, and 2TB of storage.View Deal

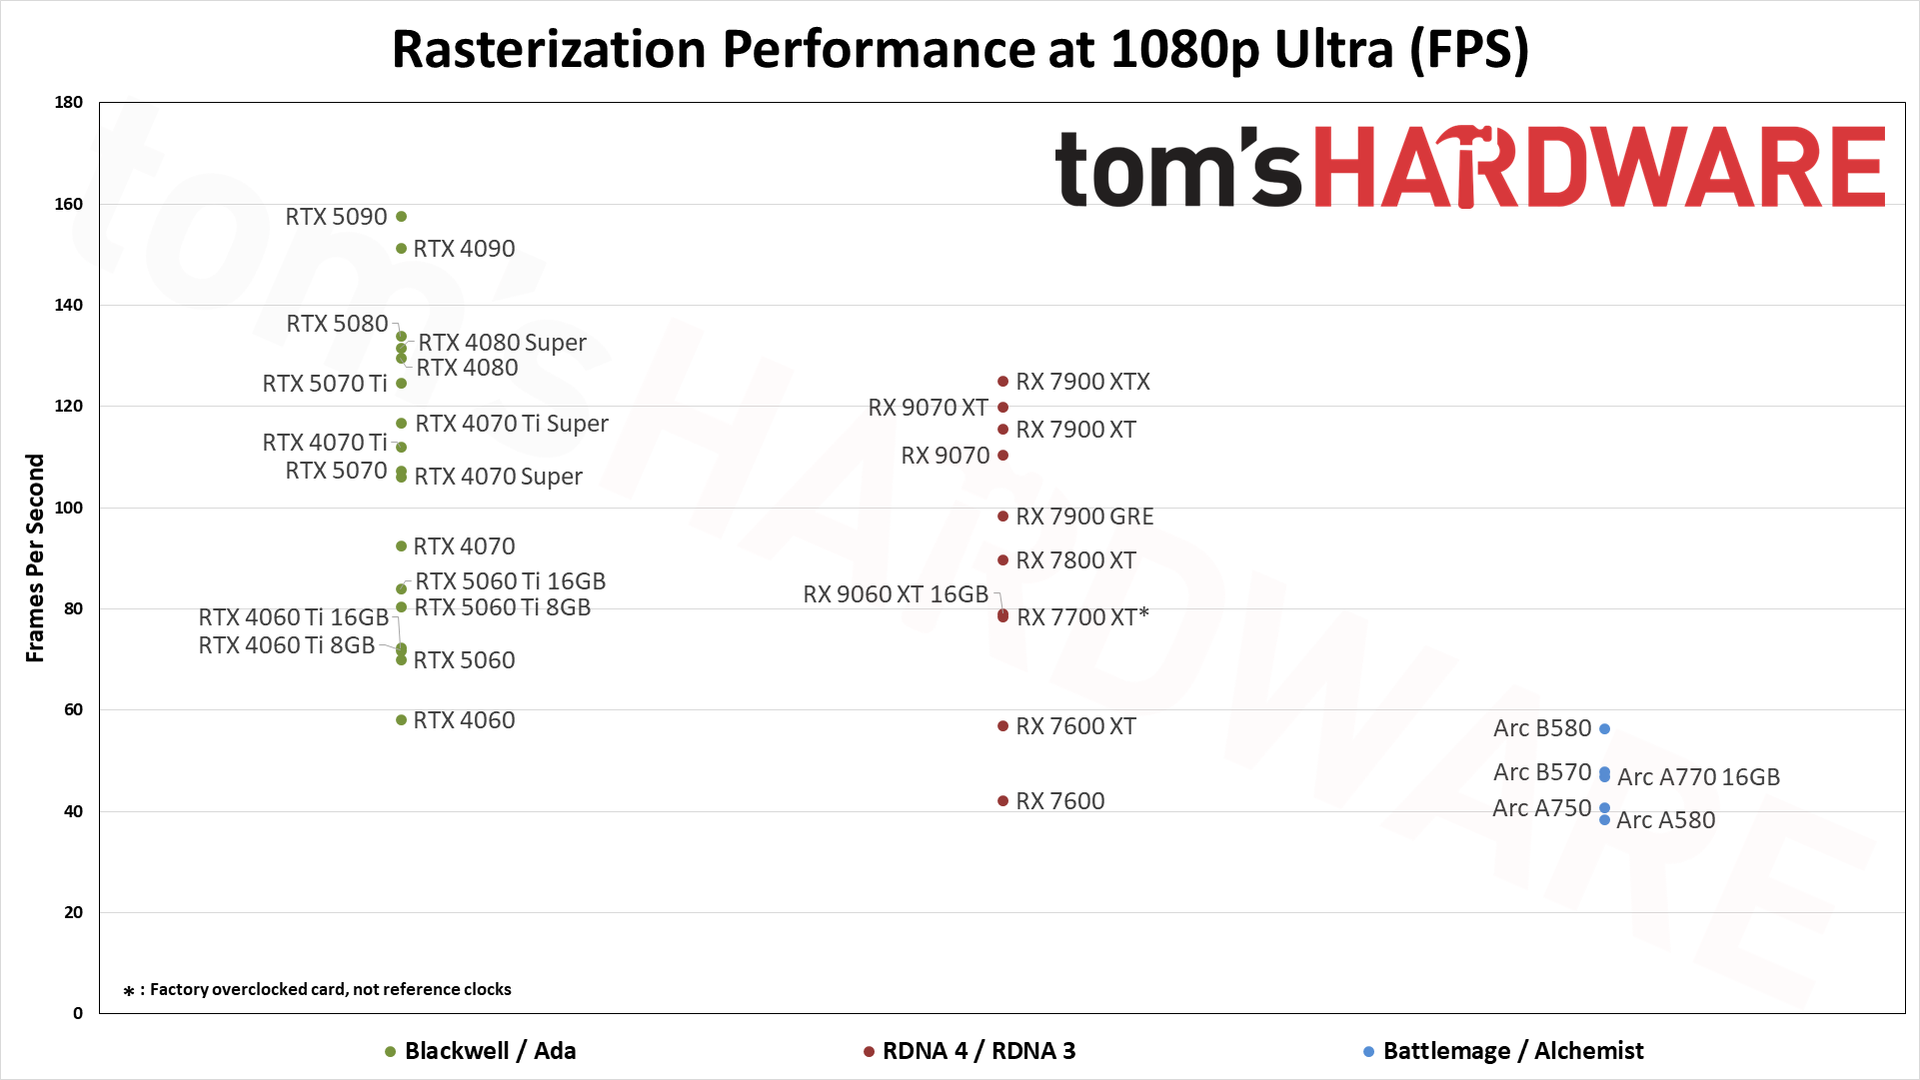
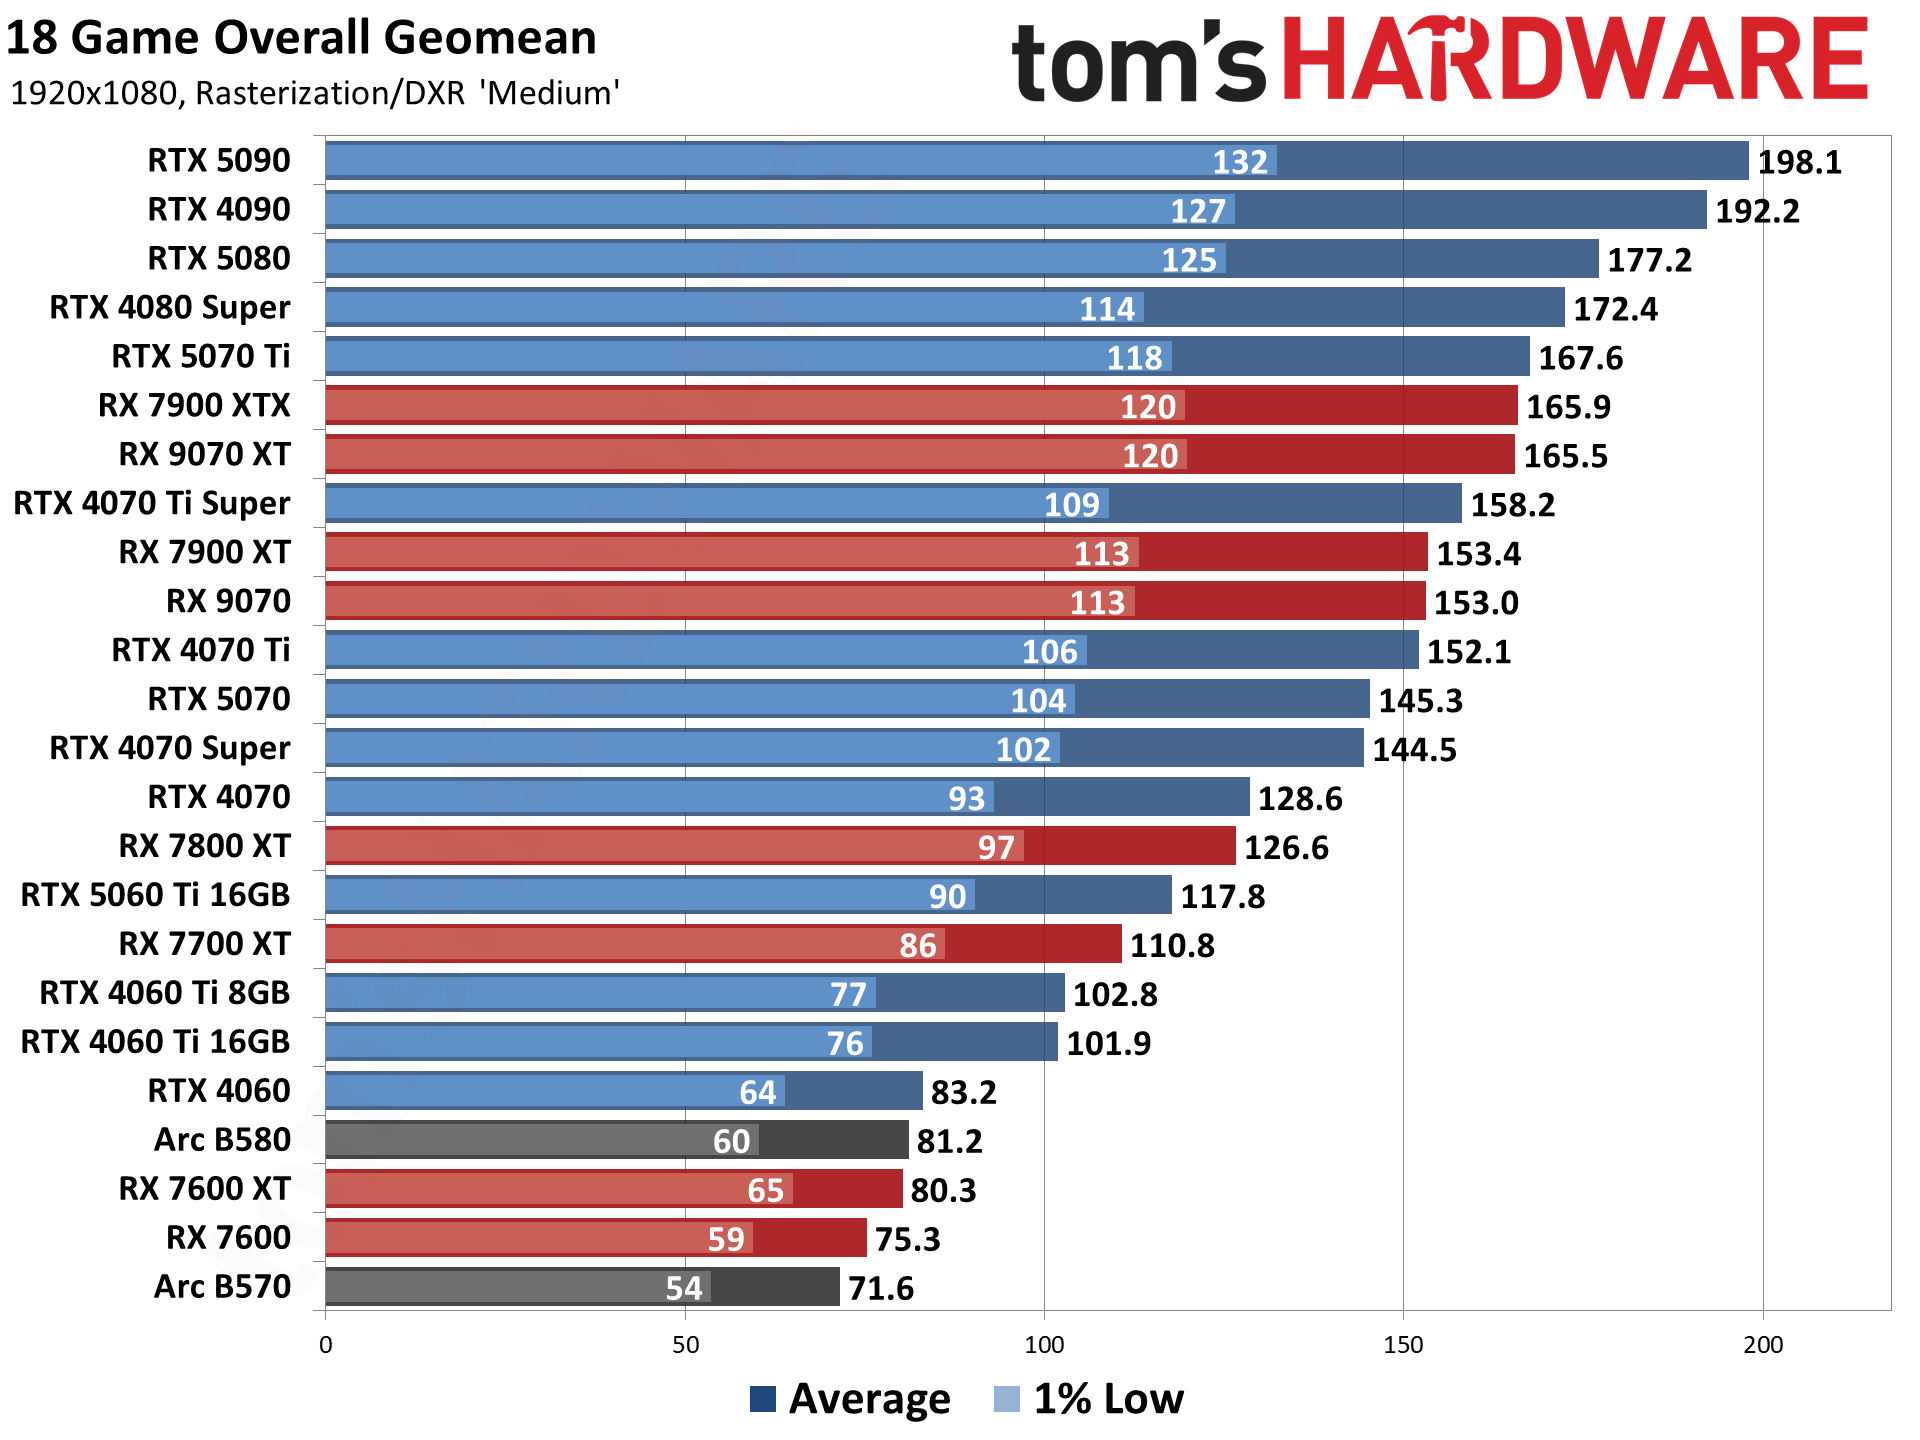
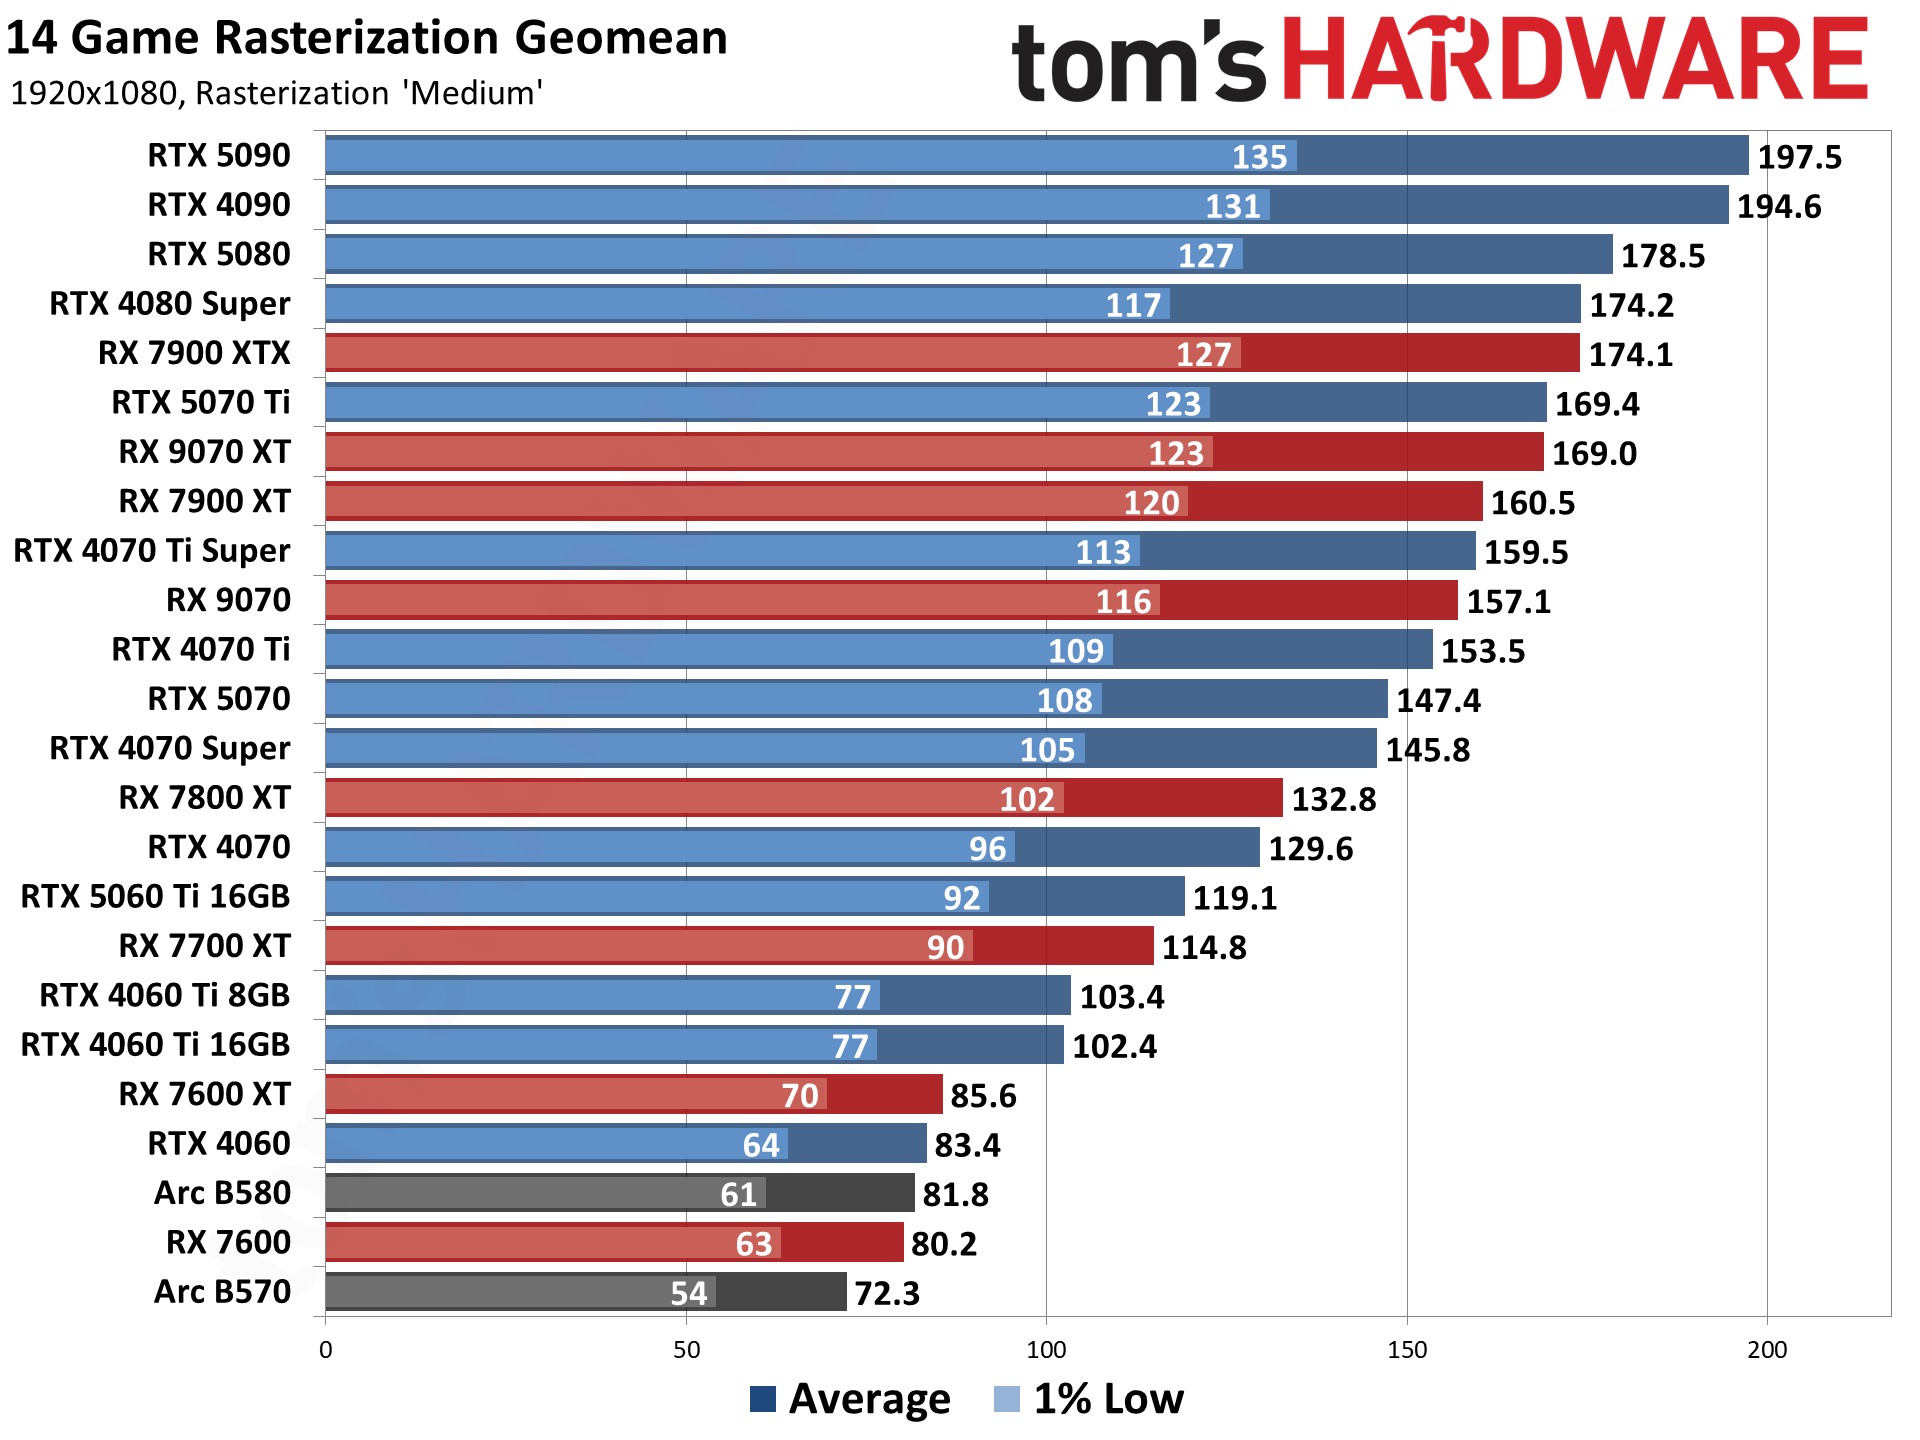
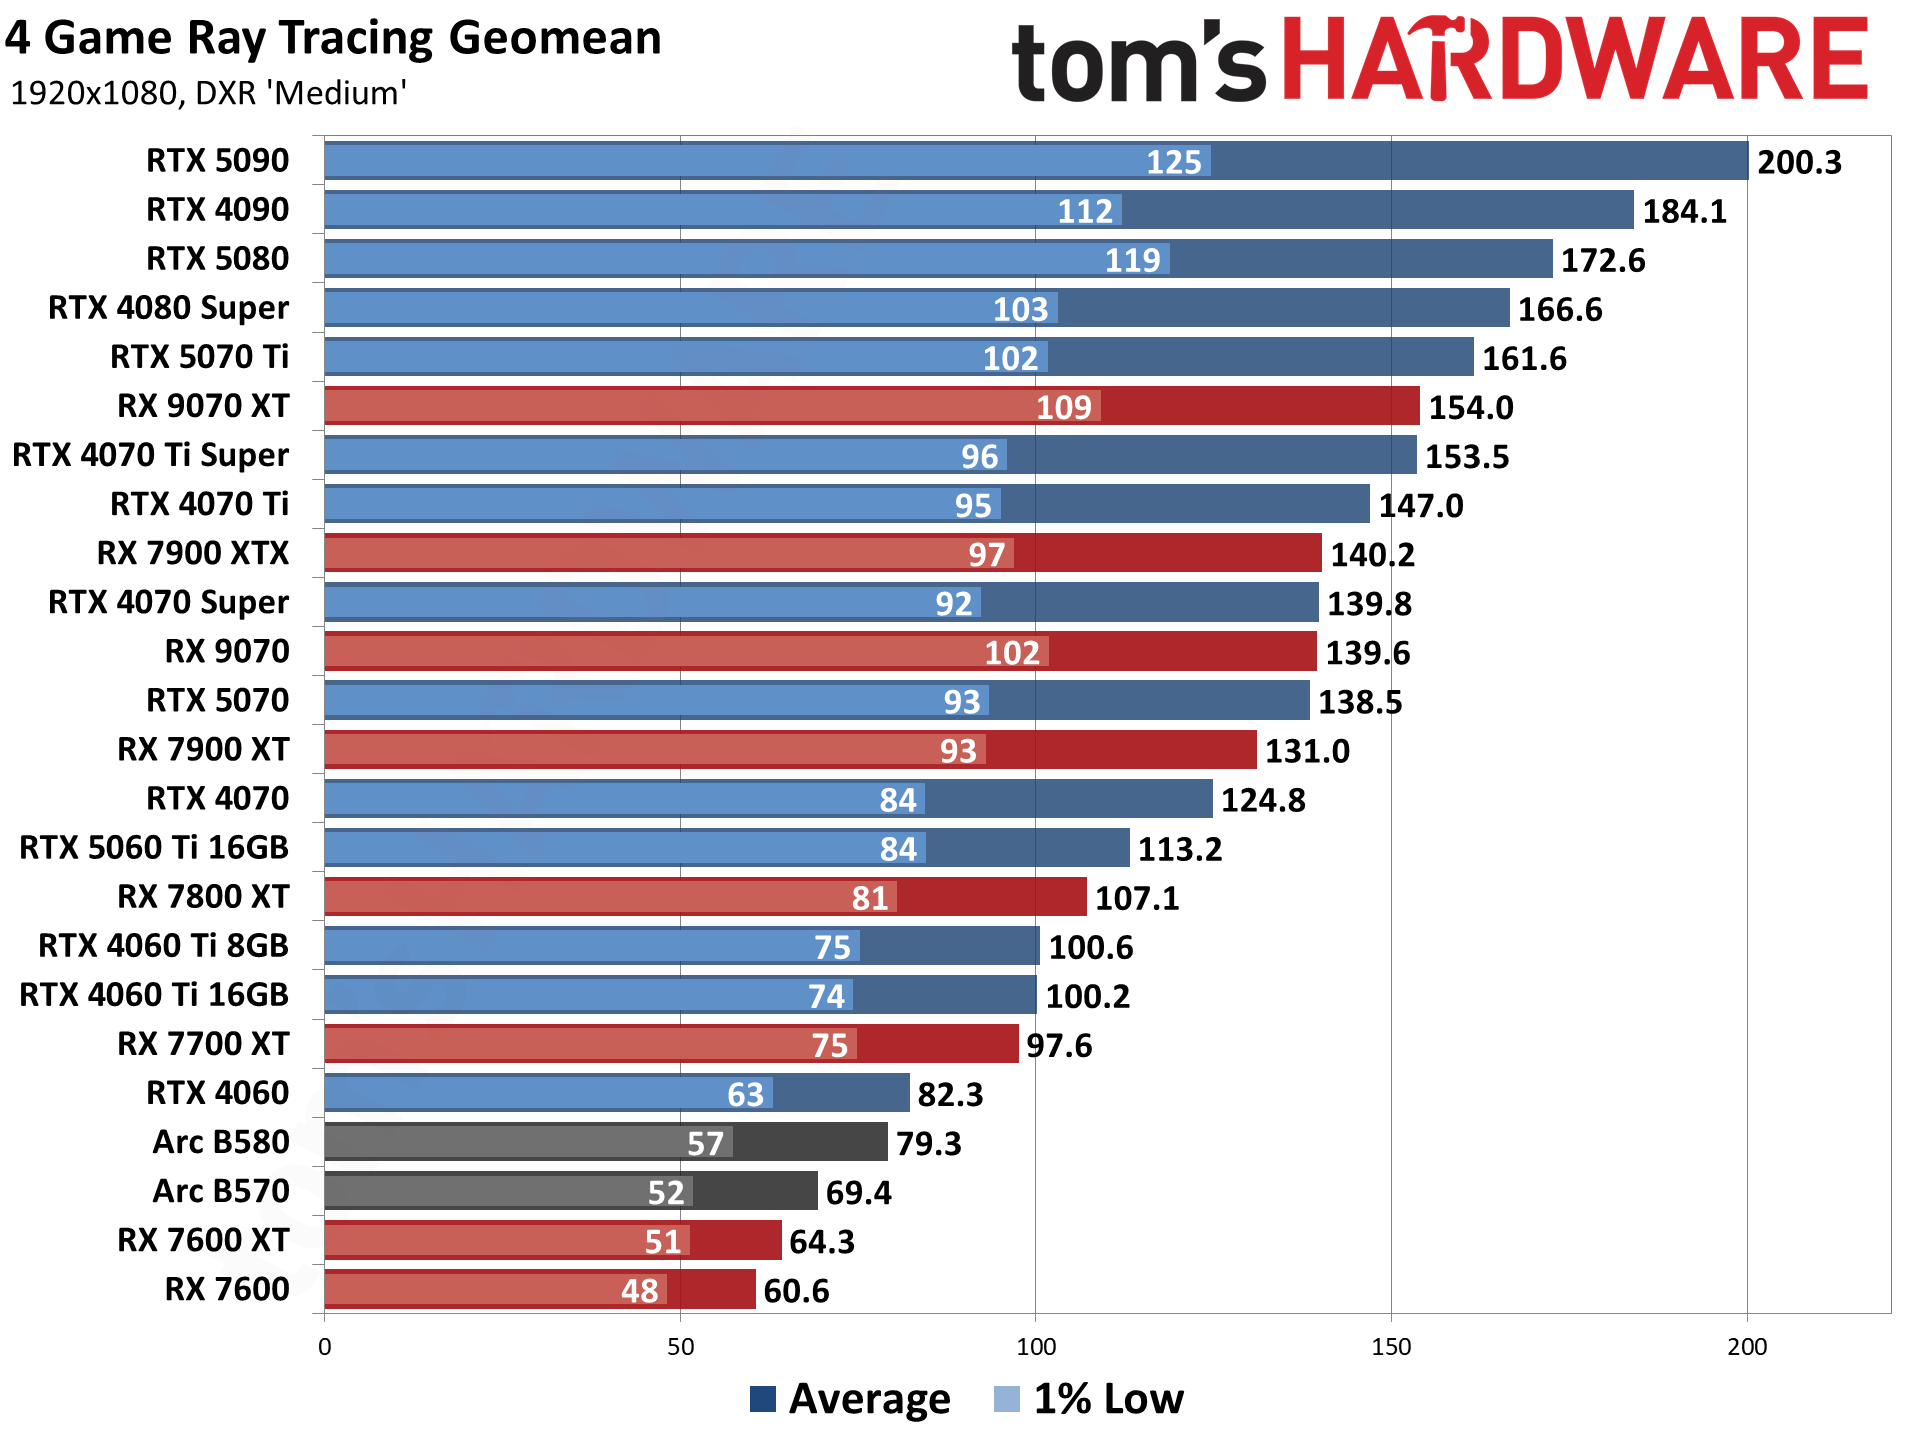
You're also getting the best value GPU in our GPU hierarchy when looking at FPS per dollar at 1080p with the RTX 5060. The 8GB of VRAM isn't as limiting as you'd think with a build like this, because you're not going to be hitting 4K here. It has more than enough power for modern games, but you'll need to occasionally optimize for the mos demanding ones. 1440p is possible in some games, too, especially with MFG switched on.

Raster performance standings for GPUs at 1080p ultra

(Image credit: Future)

As far as the CPU goes, the Intel Core i5-14400F processor is a little older these days, but still a well-sold and solid option in pre-builts at this price point. You get 10 cores, with six performance cores that offer the best performance for gaming. The other four are efficiency cores for multi-threaded work, with a clock speed that can boost up to 4.7 GHz in total.

You'd expect compromises elsewhere, especially with RAM and SSD prices flying through the roof at the minute, but you don't see that here. 32GB of DDR5 RAM is a good amount for a rig at this price, while a 2TB SSD with Gen 4 speeds leaves plenty of space for a growing games collection. Wi-Fi 6E and Bluetooth 5.3 support gives you good wireless connectivity, with gigabit Ethernet for a faster wired hook-up to your network.

You won't really see many PCs priced as well as this $1,429 MSI Codex R2 gaming PC at the moment. Yes, this spec is pricier than it was a year ago, but you could easily pay more for less in the current market. If 1080p gaming, with DLSS-supported 1440p upscaling, is all you want and need, this is the rig you'll want to buy before the $270 discount disappears.

✇Tomshardware

Original Sony PlayStation 2 security chip ‘broken wide open’ after 26 years — chemical decapping and four years of reverse engineering unlocks MechaCon secrets

作者 Mark Tyson

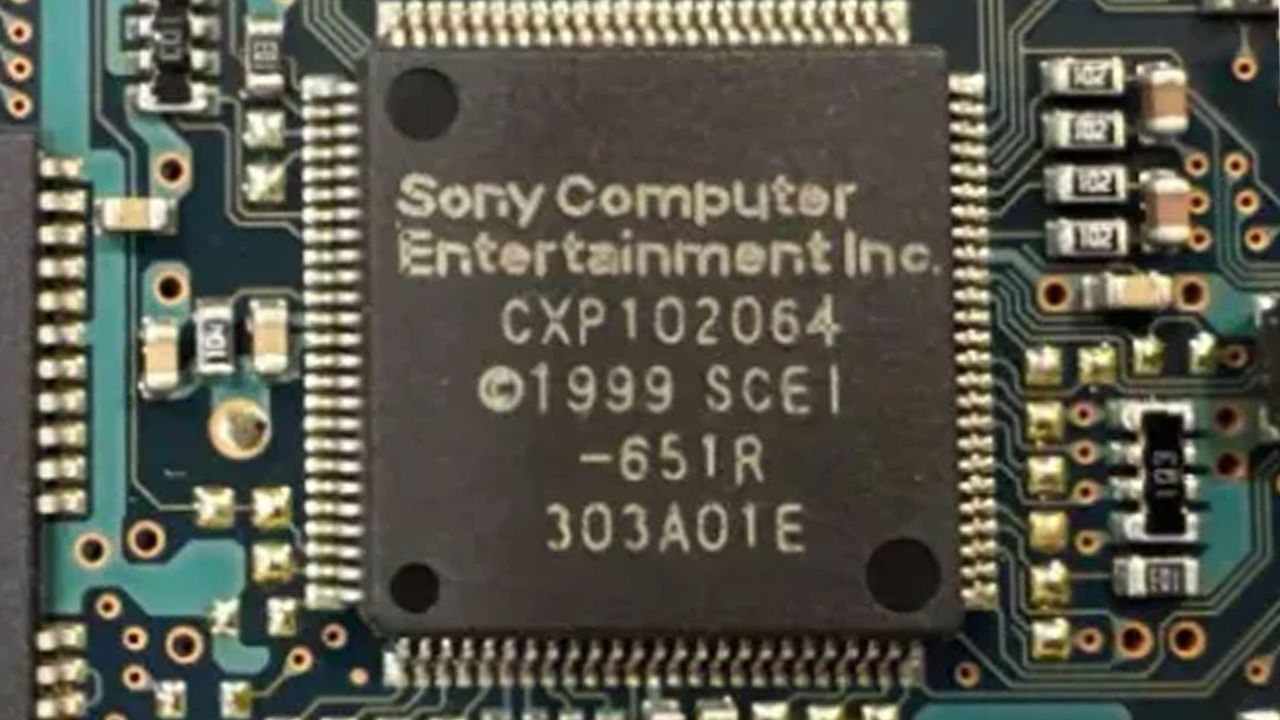
The ‘magic security chip’ inside the original PlayStation 2 has been successfully reverse-engineered and dumped. Canadian retro hardware and software enthusiast DiscoStarslayer was the manic mind behind the cracking open of the CXP102064 MechaCon chip, which arrived inside the ‘PS2 Fat’ from 1999. It took “four years of effort” to reach this stage, but this milestone should be a boon to hardware preservation, repair, and emulation projects.

After 4 years of effort, I'm happy to announce that one of the final secrets of the PS2 has been broken wide open!It's been a long process of decapping, optical dumping, and now at last a software solution.Thank you Libby for finding the exploit from our dirty optical dumps! pic.twitter.com/VrsCH8I35CSeptember 13, 2026

The Mechacon got its name from its primary duty of controlling the PS2’s optical and flash drive mechanics. It also played a significant part in Sony’s game optical disc security, supporting “Magic Gate [memory card] and KELF file [executable] decryption among other things,” notes the PSDev Wiki. Unlocking the secret workings of such chips can be important to those involved in video game preservation. So, many people will appreciate DiscoStarslayer’s work in reverse engineering and dumping one of the PS2’s last remaining secrets.

As per the social media post, the arduous task of breaking the MechaCon’s security took four years. Some of the reverse engineering tricks utilized by DiscoStarslayer include chemically decapping the CXP102064 to expose the die, then using microscopes and optical dumping skills to analyze the silicon chip circuitry. In this case, a lucky break during the hacking apparently uncovered an exploit that provided a method whereby the chip’s data could be extracted through software.

With this achievement unlocked, the game/hardware preservation and programming communities can look forward to improved emulation and homebrew developments. It should also open up possibilities for replacing the aging optical drives in PS2 consoles.

Beyond the confines of PS2 Fat consoles, some social media commenters noted that the MechaCon was also used in a handful of arcade machines from the era. Specifically, the Namco System 246 and System 256, as well as the Konami Python 1, which used modified PS2 hardware, used the MechaCon firmware to authenticate security and allow the execution of encrypted game data.

✇Tomshardware

China's open-weight AI models are now just 4 months behind frontier US offerings, Mozilla report claims — models still lag in some benchmarks but are drastically cheaper to use

作者 Shane Downing

Mozilla has published version 1.1 of its State of Open Source AI report on Sept. 15 using data current to Sept. 1, revealing that many of the best Chinese open-weight AI models are closing the gap with U.S. frontier offerings. The best open model trailed the closed leader on the Artificial Analysis Intelligence Index by three points at 60% of the price and two points behind Claude Fable 5 at 30%. Mozilla’s fit on METR task-horizon data puts the open-closed gap at around 4.4 months, in line with Epoch AI’s four-month estimate.

Mozilla is the nonprofit behind the Firefox web browser, and its report is a recurring assessment first published on July 14 on the Mozilla blog. It’s built on a Mozilla/SlashData survey of roughly 1,400 developers along with OpenRouter traffic data and third-party benchmark indices. Mozilla is an advocate for open models, and TIME reported on July 14 that Raffi Krikorian, Mozilla’s chief technology officer, described the report as partly advocacy. “Open weights” in this context means downloadable weights rather than training data or code. The report counts 16 notable open releases, but none delivers the data recipe required by the Open Source Initiative’s definition.

The four-month figure rests on METR, which is a research nonprofit that scores models by the length of task, in human working time, they complete half the time. By Mozilla’s fitted estimate, closed models handle tasks that take human experts 8 to 12 hours. Open models reach that about four months later, with open capability doubling every 3.9 months versus 5.5 for closed, by Mozilla’s computation. Mozilla also charted vals.ai’s Terminal-Bench 2.1 results, which run every model through the same harness, or software layer that offers a model its tools. On that board, Z.ai’s GLM-5.2 scored within a point of Claude Opus 4.7 and about four points behind Opus 4.8, at less than one-fifth the cost per test. On OpenRouter, a marketplace that routes developer traffic to hundreds of models, Mozilla counted eight of the top ten models by August token volume as open weights, seven of them Chinese-built. Nevertheless, closed providers took 96% of model-layer revenue on OpenRouter from May–September 2025, the Linux Foundation reported. “We see the decision to pay for closed [models] as workload-specific rather than organization-specific,” Krikorian told Ars Technica in an email.

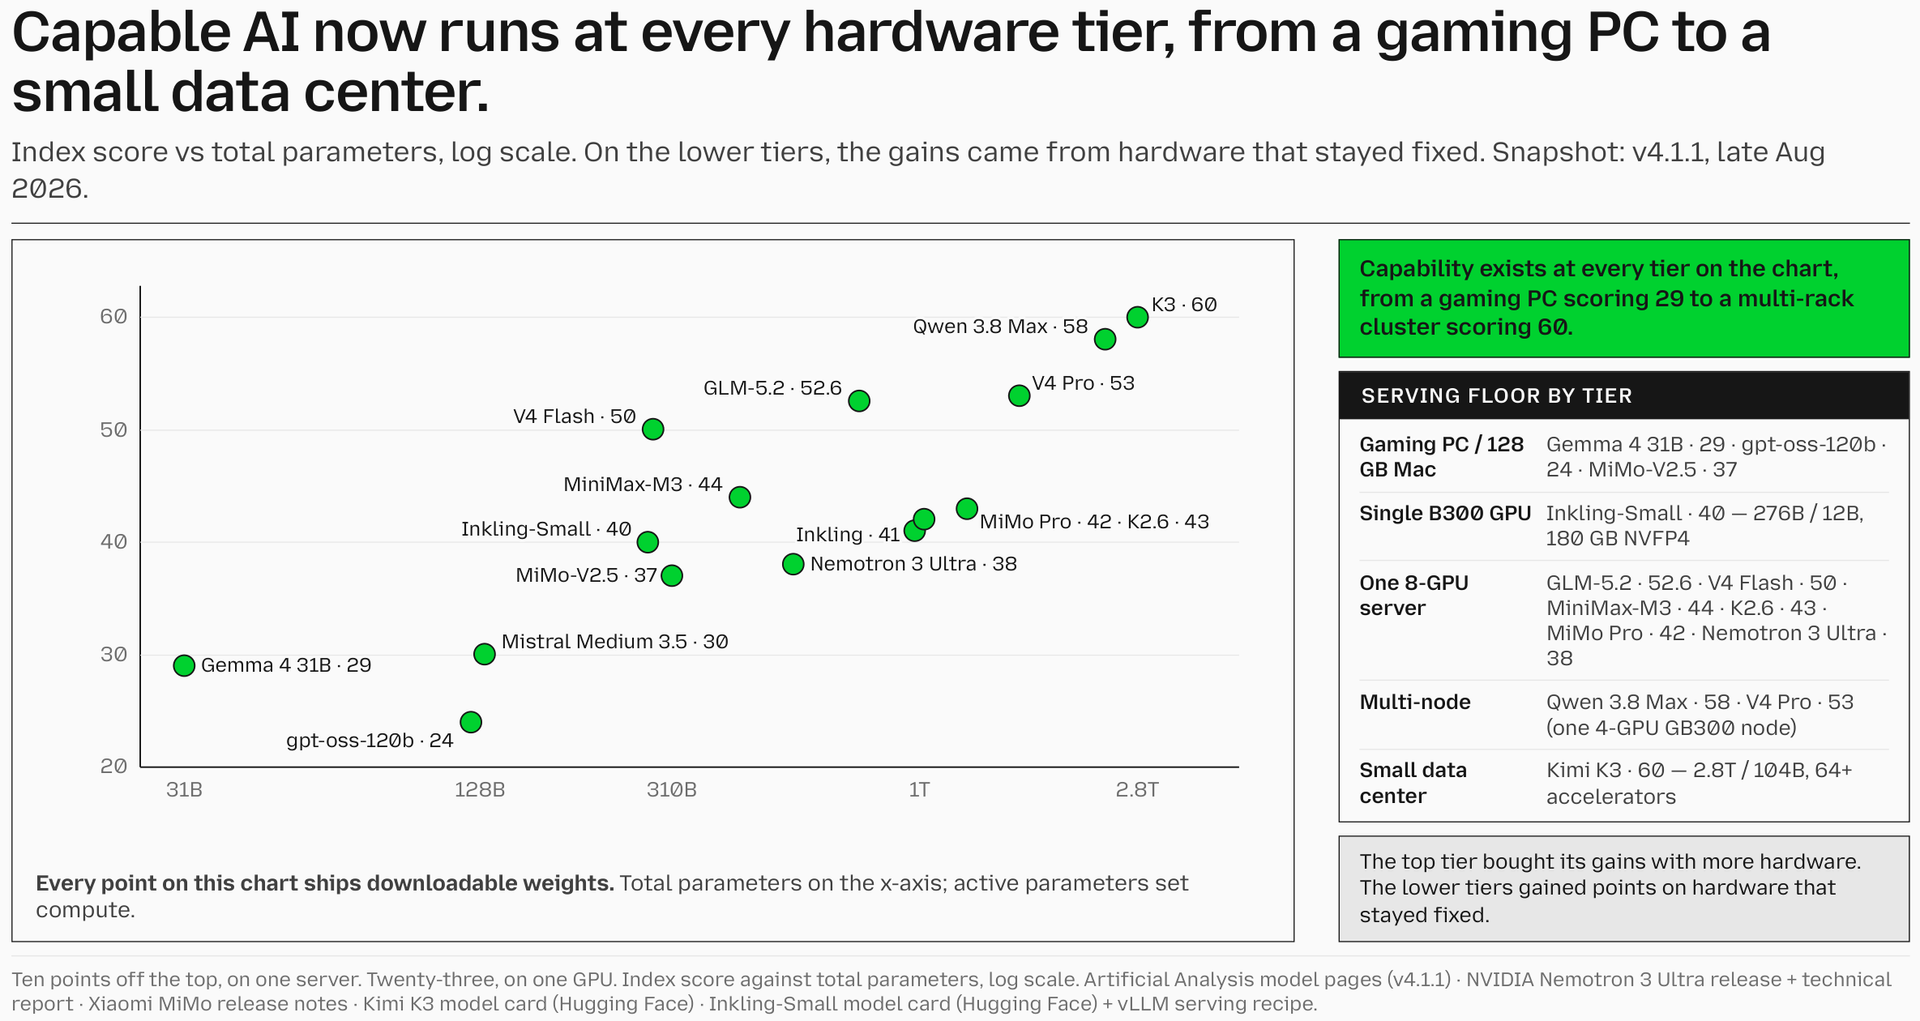
Mozilla chart of the best open-weight model score at each hardware tier.

(Image credit: Mozilla)

One caveat is that the four-month gap and the 30% token price figure are measured API to API on hosted endpoints and at list price. The report’s own hardware chart puts the best open model that fits one server at 52.6 and the best on one GPU at 40. The drop from the top is 10 and 23 points, respectively, a larger gap than the reported four months. Kimi K3’s native MXFP4 checkpoint runs about 1.56TB across 96 shards, and Mozilla’s serving configuration lists 64 or more accelerators, while vLLM calls for at least eight GB300 GPUs, with multiple nodes for production traffic. The report describes this as open but not runnable by most who hold it, and Tom’s Hardware put the memory need near 1.5TB in July. One example exception is Thinking Machines’ Inkling-Small model, under the Apache 2.0 license, whose NVFP4 version fits one B300 at a 180GB floor.

The report’s data stops at Sept. 1. Since then, Artificial Analysis has moved its index to v4.3 with a different evaluation set. The live board has Claude Fable 5.1 at 53 on its highest effort setting with Kimi K3 at 44, not comparable to the v4.1.1 numbers Mozilla plotted. vals.ai’s Terminal-Bench 2.1 board, updated Sept. 11, is now led by GPT-6 Astra at 87.27% with Fable 5.1 at 85.02%. Mozilla’s own chart caption reads: “the gap resets every release cycle.” K3 also carries an allegation detailed in the Sept. 8 NSA/CISA/FBI joint advisory (AA26-251A). The claim, which Mozilla’s report states as “asserted, and unshown,” is that Moonshot extracted Claude Fable 5 data to train K3 through distillation, the practice of training one model on another model’s outputs. On July 17, Artificial Analysis had K3 at 57 versus Fable 5’s 60, while on Sept. 1, Mozilla had it two points back.

✇Tomshardware

Devastated father says his 9-year-old son spent $118,000 on YouTube ad campaigns for his Minecraft channel using a company credit card — bill racked up in just three weeks was supposed to be one $20 promotion

作者 Shane Downing

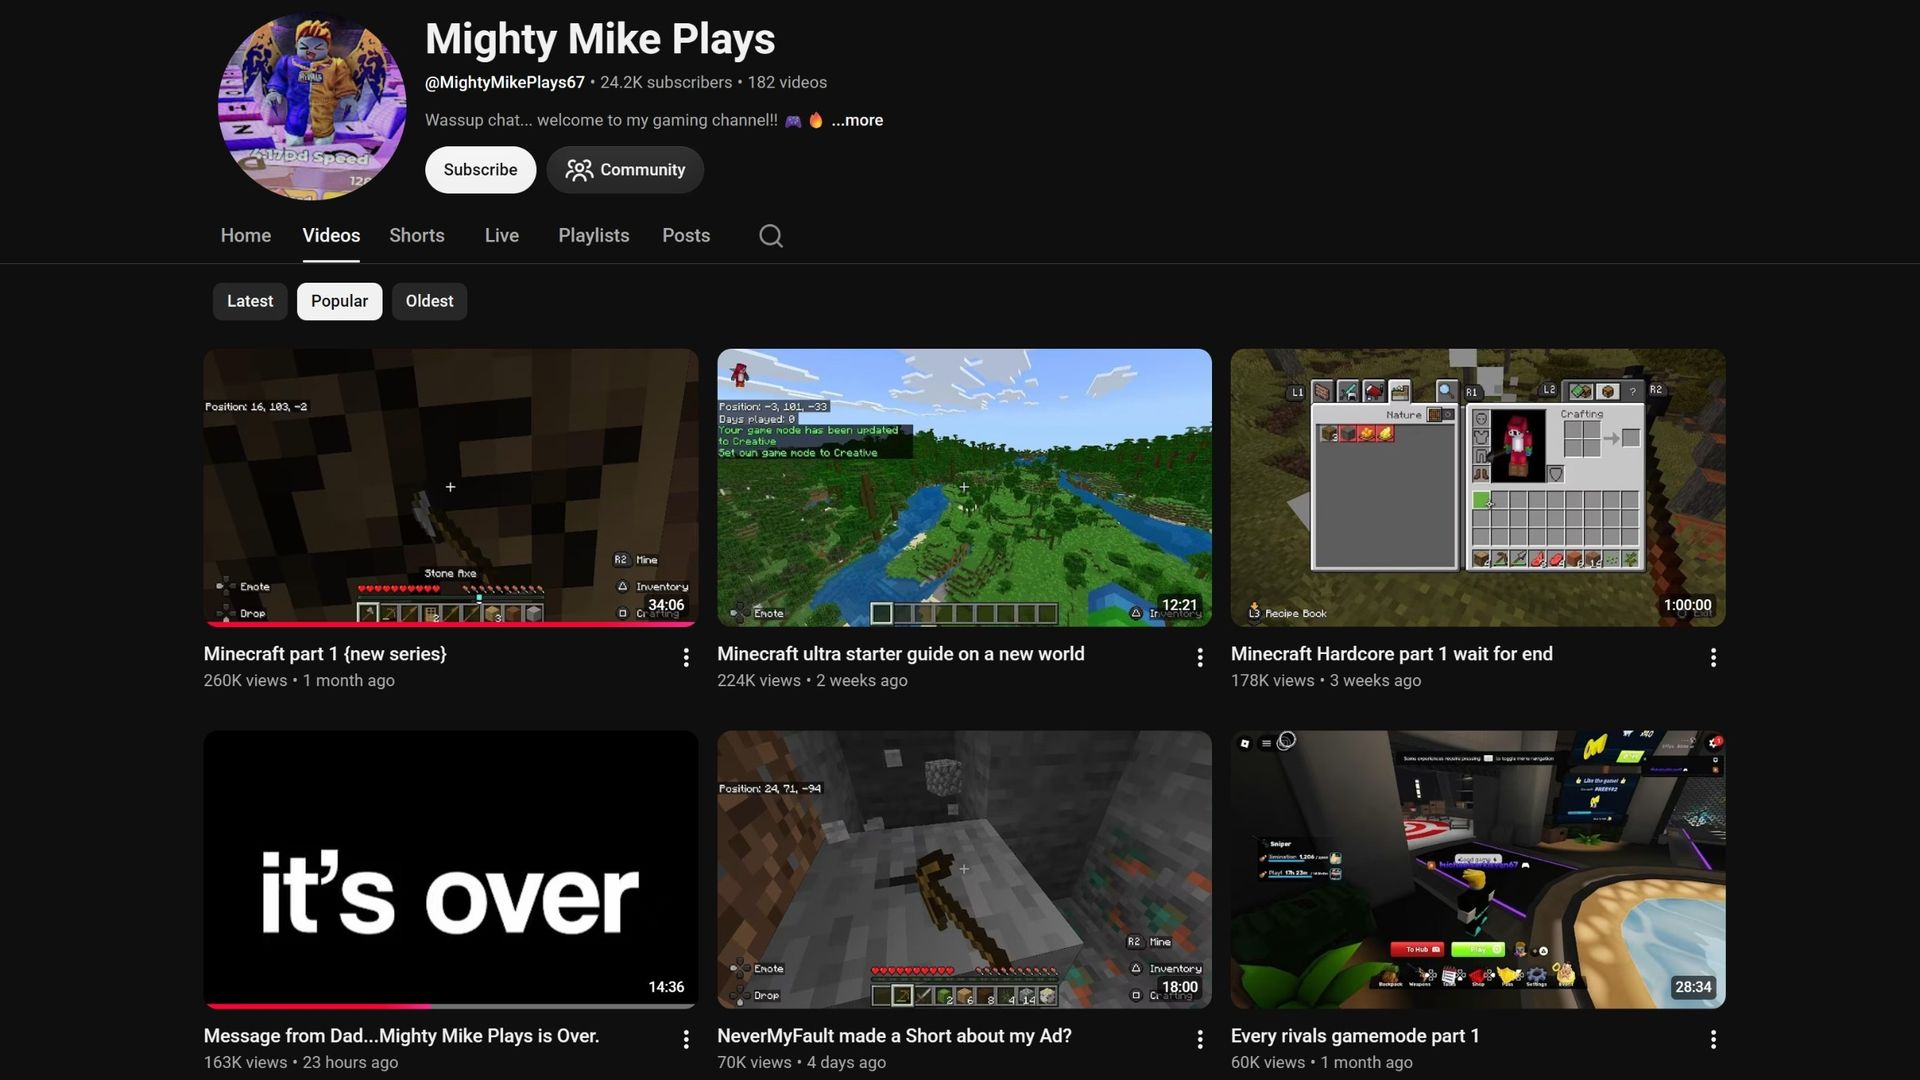
A father says his 9-year-old son spent $118,000 on YouTube ad campaigns for his Minecraft and Roblox gameplay videos over about three weeks, all charged to a company credit card the father had saved to his own Google account, which his son also used. The father, who identifies himself only as Dave, described the incident in a video titled “Message from Dad…Mighty Mike Plays is Over.” posted to the boy’s channel on Sept. 15. Dave said he was called into a meeting with his manager, corporate staff, and finance and shown the advertising charges.

Mighty Mike Plays (@MightyMikePlays67) is a 9-year-old’s Minecraft and Roblox gameplay channel with about 24,000 subscribers and 182 uploads as of early Sept. 16. Dave said it started when the boy was around 8, streaming straight from a PS5 with a cheap headset and no editing. Early videos got 5 to 11 views, he said. Dave said he entered the company card himself to buy Robux for his son, and it then sat saved on the Google account that also carries his work email, calendar, and files. Dave did not say why he used the company card for that purchase.

Dave said that after the boy complained about views, he set up a roughly $20 promotion and talked through the steps aloud: set a budget, select who sees the ads, hit run. The boy then created his own campaigns, and Dave said his son did not understand the $20 as a limit. “The credit card, it just says approved every single time,” Dave said in the video. Finance showed him three weeks of ad spend totaling $118,000 on campaigns titled “Mighty Mike,” “Epic Roblox,” and Minecraft gameplay.

Three of the promoted videos reached around 200,000 views. As of a check at 12:26 a.m. ET on Sept. 16, the channel’s three most-viewed gameplay videos stood at 260,000, 224,000, and 178,000 views, with a run of uploads above 1,000 views and most of the rest under 100. Four days before Dave’s video, the boy had posted a video titled “NeverMyFault made a Short about my Ad?” about another creator noticing one of his promotions; it had about 70,000 views.

The Mighty Mike Plays channel's Popular tab as of 12:26 a.m. ET Sept. 16.

(Image credit: YouTube / Mighty Mike Plays)

Dave said the matter has been escalated and he does not yet know whether he will get to keep his job or have to repay the costs.

Google’s own help pages say a payment method entered for any Google purchase is stored in a payments profile tied to the Google Account and is offered again for the next purchase. The profile is also shared across Google Ads and other Google products. YouTube’s Promote tool, which Google describes as a simplified version of Google Ads, walks a creator through a goal, an audience, a budget, and an end date. Dave did not say which interface his son used, but the steps he described match Promote’s. Google Ads does not allow users under 18, but the account was the father’s.

In a separate case, the FTC announced on Sept. 4, 2014, that Google would refund at least $19 million to parents billed for children’s unauthorized in-app purchases on Google Play, and required it to get express consent before billing. That covered Google Play, not Google Ads. Dave said the family will remove saved payment details, add spending caps, and set up parental controls, and that the channel is paused until “real guard rails” are in place.

✇Tomshardware

AI enthusiast builds GPT-6 Astra-powered bot to take on Balatro's Gold Stake Black Deck — bot leverages Python for numerical tools, beats hardest difficulty repeatedly

作者 Oliver Haslam

A Reddit user has shared details of a new bot that has beaten the devilishly difficult Gold Stake Black Deck in Balatro, a poker-like video game. The Redditor, who works in the AI industry, says that they have been testing the bot and "obtaining some crazy results" — and they've even shared a YouTube video highlighting how they went about creating the card shark of a bot.

In a post in the /balatro subreddit, user Atol8 (real name Jacopo Attolini) initially claimed the bot was the first of its kind to reliably beat Balatro. They subsequently admitted that "reliably might be a strong word," adding that the bot has "repeatedly beaten Balatro."

My Balatro Bot just won at Gold Stake Black Deck
 from r/balatro

Beating Balatro in this instance meant beating the Gold Stake Black Deck, a combination that is widely considered to be the most difficult in the game. On its own, the Black Deck includes +1 Joker slot, but reduces the player's available hands by one per round. The Gold Stake effect introduces cumulative difficulty modifiers from all prior stakes, plus reduced hand sizes and stricter economic penalties.

Combining these two together makes for a brutal economy and more than a little luck, with players relying on strong early-game RNG.

In a post in the /balatro subreddit, user Atol8 (real name Jacopo Attolini) initially claimed the bot was the first of its kind to reliably beat Balatro. They subsequently admitted that "reliably might be a strong word," adding that the bot has "repeatedly beaten Balatro."

Beating Balatro in this instance meant beating the Gold Stake Black Deck, a combination that is widely considered to be the most difficult in the game. On its own, the Black Deck includes a +1 Joker slot, but reduces the player's available hands by one per round. The Gold Stake effect introduces cumulative difficulty modifiers from all prior stakes, plus reduced hand sizes and stricter economic penalties.

Combining these two together makes for a brutal economy and more than a little luck, with players relying on strong early-game RNG.

The bot itself is based on OpenAI's Astra models, which were released earlier this month. GPT-6 Astra has already grabbed headlines, having completed Valve's iconic Portal in 24 hours.

In a GitHub post detailing the ins and outs of the bot, Attolini says that GPT-6 Astra takes care of making strategic decisions based on the deck it has built. But the bot also relies on good old Python for its numerical tools. The legality of each move is assessed by BalatroBot, a separate tool that exposes Balatro game states and controls for external programs to interact with.

As impressive as this is, don't be fooled into thinking this bot played the perfect game. Reddit commenters have been quick to point out that it made some "interesting blunders" throughout its playthrough. Despite that, GPT-Astra is OpenAI's latest flagship model, with the company claiming it offers “a new generation of intelligence,” and “is state-of-the-art on computer use, browsing, software engineering, cybersecurity, science, and professional work.”

Not all bots are great at playing games, though. Just last year, OpenAI's ChatGPT "got absolutely wrecked on the beginner level” while playing Atari Chess. Elsewhere, Google's Gemini didn't even get as far as starting its own chess battle with the Atari 2600it ditched the game after deciding that it would "struggle immensely" against the iconic home console. It seems that, sometimes at least, even modern tech can't compete with a 1979 Atari 2600 game.

Google Preferred Source

✇Tomshardware

AI leaders clash over safety fears after Anthropic whistleblower says AI could 'kill us all' by 2030 — OpenAI, Anthropic and xAI figureheads call for external governance, while Jensen Huang says worries are 'made up'

This past week, employees and key figures at leading AI companies have called for a slowdown in the development of frontier AI models, citing warnings from their own teams and other AI researchers that the risk stemming from a super-intelligent AI could endanger the human race. However, while the top Western firms have shown solidarity on this issue, others have urged caution or downright denied their claims, but there's a deeper story within the calls for a slowdown, namely the tension between open-source and closed-source AI models.

Nvidia CEO Jensen Huang said the safety fears were "made up," and that there was no need for a slowdown. Chinese officials called the claims "fearmongering," and an effort to stymie international AI development efforts, while President Trump waded in with characteristic bombast and said that he was enough of an AI safeguard on his own, and that it was in the interests of China to enact a frontier AI slowdown

Meanwhile, other countries are reacting to the news and taking independent efforts to investigate AI safety, with the UK's King Charles setting a meeting with leading AI figureheads to discuss how to better develop AI for the benefit of humanity.

Why now?

If you ask most workers who've been scared into believing their livelihoods were in jeopardy, the time for AI slowdowns came and went years ago. Indeed, many are nostalgic for the time before AI. But why are so many tech leaders only now raising the alarm?

They claim it's entirely based around safety fears. Following months of AI seemingly surprising their own developers by breaching sandboxes to go on exploit-hunting sprees. The volume of concern rose considerably after former OpenAI researcher, Jacob Coxon, resigned from Anthropic, claiming that none of the AI companies were taking AI safety and alignment seriously enough.

He didn't whistleblow on anything nefarious, dump documents or internal company data to prove his claims, or point to any specific attack vectors, or even actual harms. Instead, Coxon warned of a future potential of AI that he sees these companies racing towards without due concern.

What they're developing could, "kill us all by the end of the decade," he warned. It's not clear how, but it started a viral conversation all the same. Much like Matt Schumer's "Something big is happening" viral post from February this year.

Days later, OpenAI CEO Sam Altman, Anthropic CEO Dario Amodei, and Elon Musk showed surprising levels of solidarity for arch rivals in the space, putting out similar statements claiming that AI was becoming too powerful and that a general slowdown in the development of frontier AI models was the best solution.

Dario is right https://t.co/EwKgqQGaUoSeptember 12, 2026

Claiming that AI was playing an increasing role in improving itself — hinting at the recursive self-improvement (RSI) event that many AI researchers are concerned about — Amodei called for the creation of independent auditors for AI models. Altman agreed, even calling on governments to globalize the regulation to encourage unified compliance with any safety protocols enacted by the frontier developers.

Where we're going, we don't need roads

Not everyone feels these fears are warranted, however. China, which has recently made great strides in its development of highly intelligent open-weight models, called the concerns "fearmongering" and said it served no one's interest to be so confrontational. Although Chinese Premier Xi Jinping has said in the past that it was important for AI to "always remain under human control," the Chinese state-run Global Times paper called demands for a slowdown a method to "contain" Chinese developments.

Meanwhile, Nvidia CEO Jensen Huang has broken ranks with other Western AI leaders, claiming that there was no need for a slowdown and that any apocalyptic fears around AI were entirely fictional.

Nvidia CEO Jensen Huang was asked how to explain a claimed 10% risk of human extinction from AI.“We shouldn't, because it's made up.” "All of these predictions have been wrong" pic.twitter.com/TZ3EXL8cl1September 14, 2026

As one of the few companies making real — and enormous — profits from AI development, Nvidia has a vested interest in the expansion of the AI industry continuing on its current explosive trajectory. Indeed, it has heavily invested in it. Nvidia has stakes in hardware and software companies, along with providing backstops for neo-cloud firms. It also recently bought Hugging Face for $13 billion.

We've been here before

While the AI CEOs might have suddenly decided it's time to slow down, there have been many, many others who have made that call before now. U.S. Senator Bernie Sanders has been at the forefront of claims that the AI industry was moving too fast and breaking too many things, and recently called for heavy prison sentences for those developing superintelligent AI.

Over 1,000 AI workers signed an open letter in July this year calling on the U.S. government to control AI research and ensure safety and security. Others did that in 2023, too. This isn't even the first time that AI CEOs have called for slowdowns on AI development. Dario Amodei called for global coordination to police AI after the release of OpenAI's GPT2 model in 2019. Elon Musk did the same in 2023.

None of this takes away from the real dangers of AI, or the suggestion that now may really be the time to do something about them. But it does raise questions about the reasons behind their coordinated fear-raising. Even if it isn't fear-mongering.

Safety, or a trojan horse?

The collation of leading Western frontier AI companies clamoring for tighter controls over powerful AI models has another theoretical benefit too: containing the number of AI models that are permitted for use in the Western Hemisphere. A cursory look at OpenRouter's AI model rankings, which base themselves on the total number of tokens generated, places just three Western-made models on the top ten list — the heavily discounted GPT 5.6 Luna at number one, Nvidia's Nemotron Ultra 3 (Free) at number eight, and Google's recently-launched Gemini 3.8 Flash at number ten.

The rest of the models in the rankings are all open-weight Chinese models, which, more often than not, are cheaper than leading Western frontier models, according to the Artificial Analysis' Cost per Intelligence index. The Chinese models in OpenRouter's current top ten include Z.AI's GLM 5.3, Deepseek V4 Flash, and Tencent's Hy4 and Hy3. So, if the development of a Western frontier AI alliance emerges under the guise of calls for safety, it's possible that said companies are aiming to be the chosen few, creating a closed-loop monopoly for "preferred" AI providers. However, this remains speculation as the situation develops.

Will anything actually change?

Although the major AI companies may voluntarily, or even jointly, throttle their development efforts to improve safety, enacting anything globally significant will need the cooperation of international governments. There are certainly calls from politicians the world over to rein in the trillion-dollar companies and their cutting-edge autonomous systems.

But with the U.S. government firmly on the side of limited regulation, and no clear indication of what a slowdown would even look like. Would that entail limited compute? No new models? A halt to superintelligence research? It's hard to imagine a global consensus taking shape as things stand.

✇Tomshardware

Asus' ludicrous $10,850 20th-anniversary bundle is now the cheapest way to buy an RTX 5090 — Nvidia's flagship GPU stock is so limited that this bundle with a 3000W PSU, X870E board, and open-frame case is actually cheaper than some scalper listings

作者 Ben Stockton

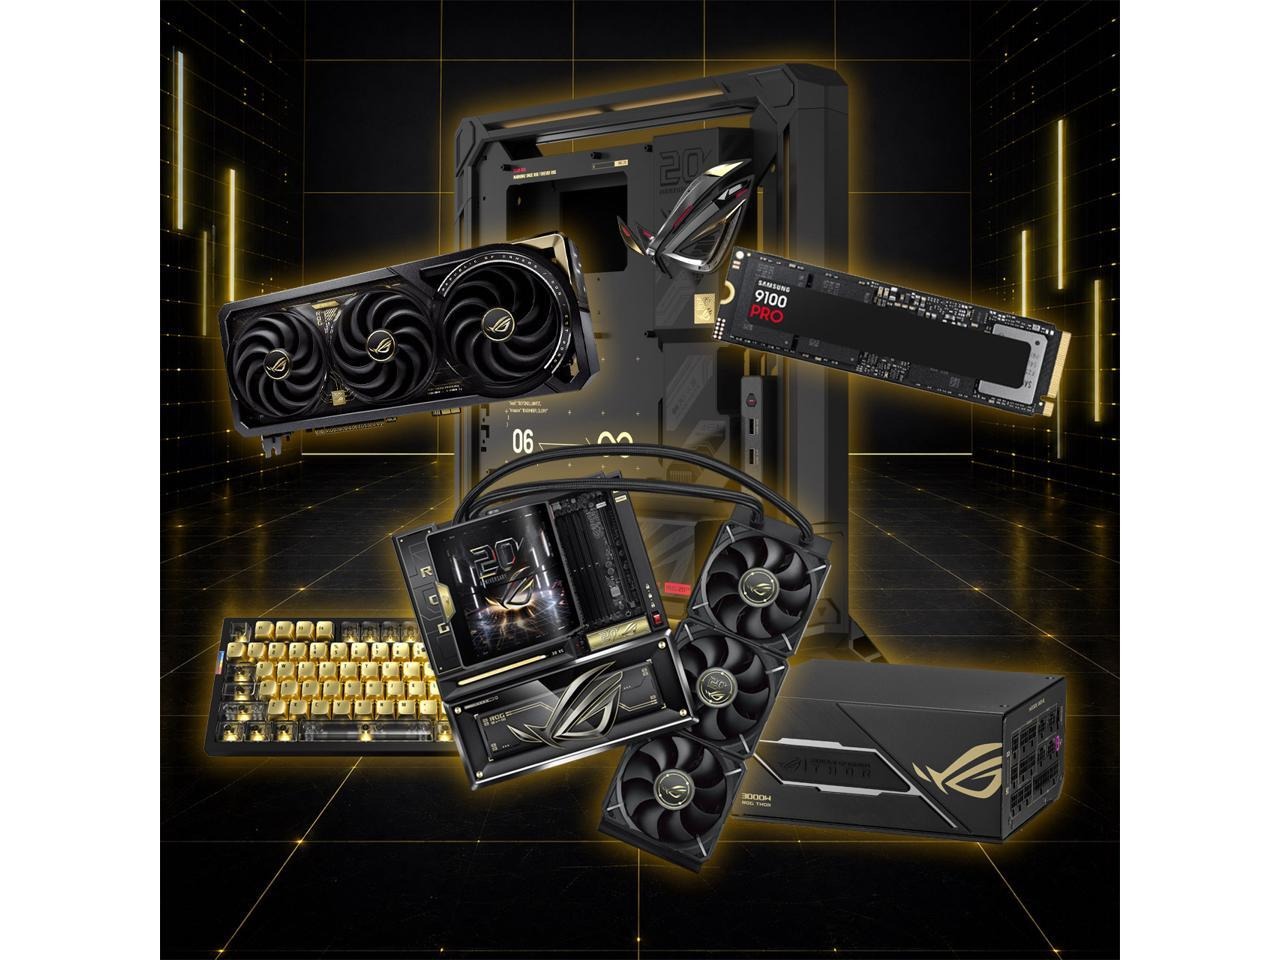
We've reviewed Asus' ROG Edition 20 anniversary kit. We've built a PC with it. It's about as premium as a gaming PC build can get. Right now, you can pick up the same kit for a whopping $10,849.96 on Newegg in a combo deal. To put it mildly, this is one expensive deal, but it's actually hiding a secret gem: it's the cheapest RTX 5090 graphics card on sale right now.

Check out this deal at Newegg

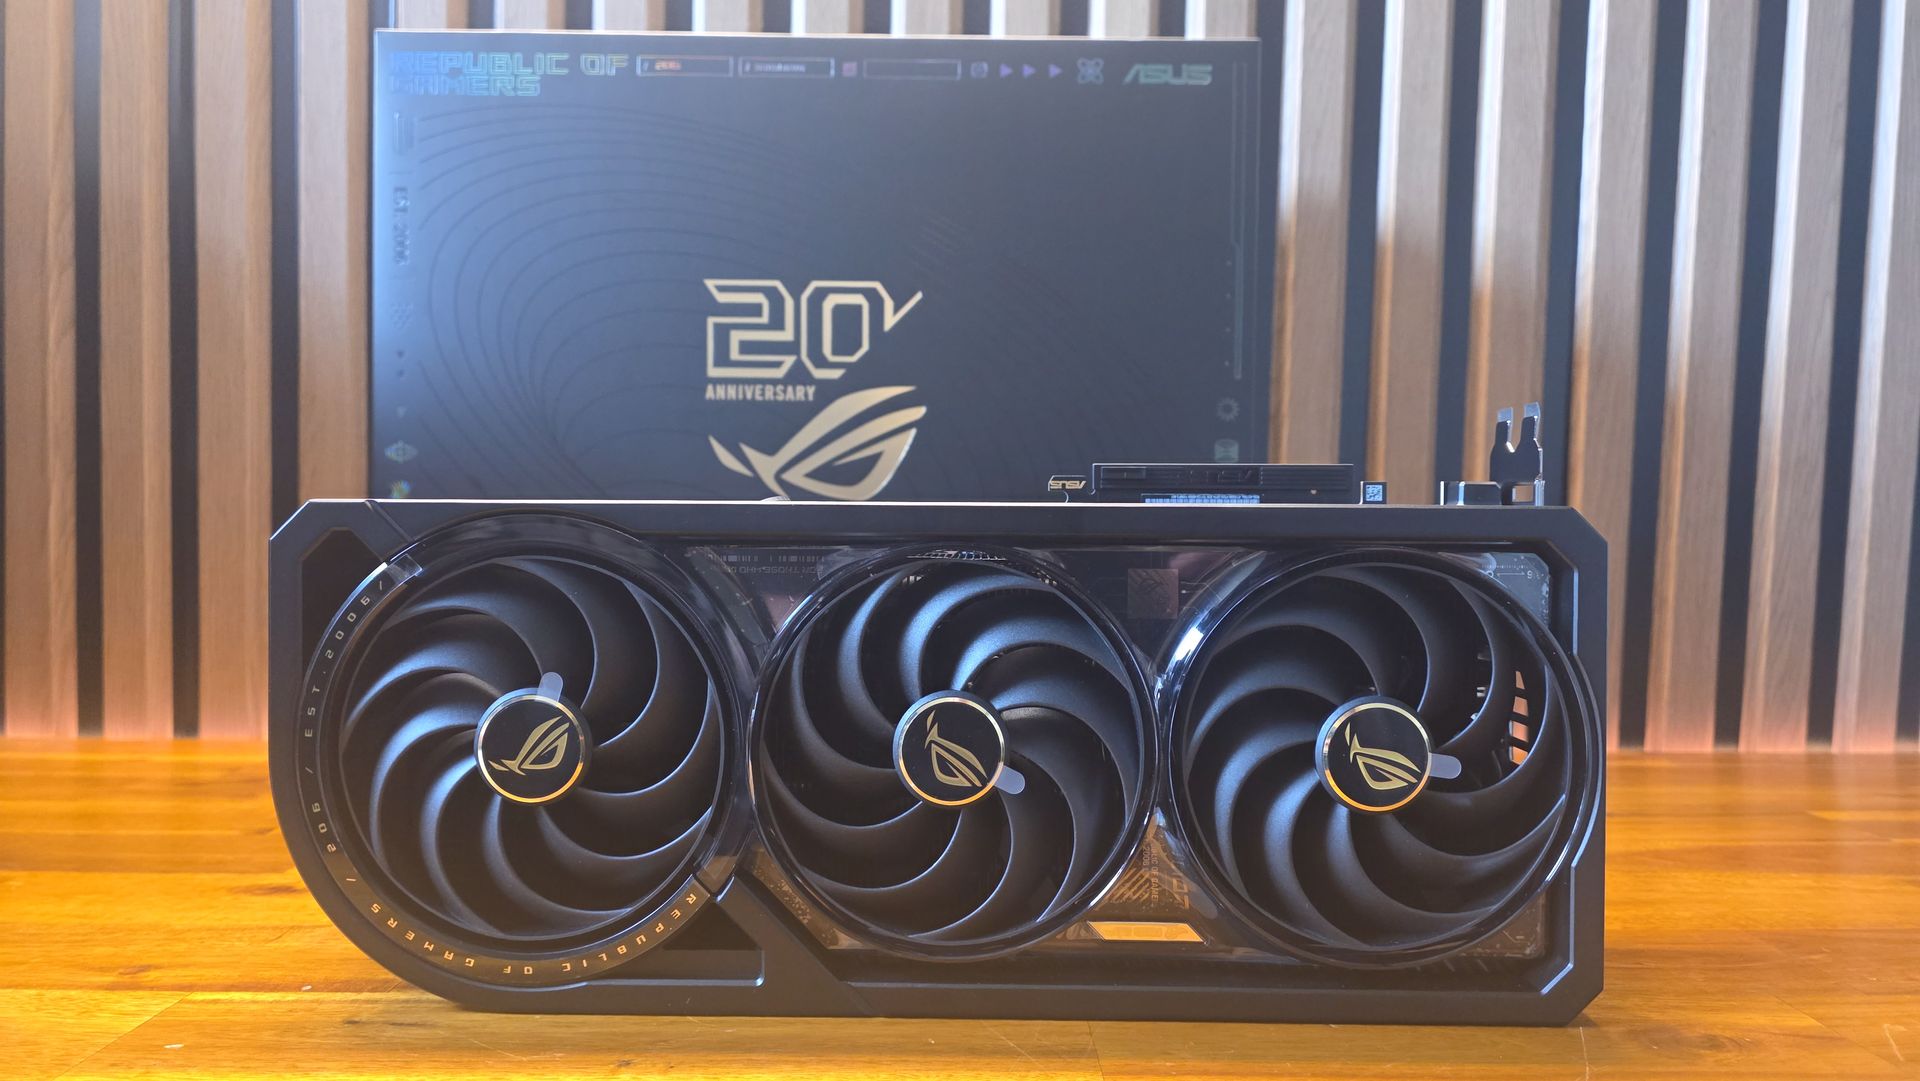
Writing up a near-$11,000 combo set as a deal might seem silly, but one of the core components here is the Asus ROG Astral GeForce RTX 5090 Edition 20 that is priced as part of this deal at $5,999. You can't buy this Astral card on sale individually right now. In fact, you can barely buy an RTX 5090 anywhere. RTX 5090 stock has almost completely disappeared in the United States, with only sketchy third-party sellers offering it at prices approaching $10,000.

This premium GPU is now ultra premium and, for the time being, ultra rare. Does that make this $10,849.96 Newegg combo deal a good option? If money is no object, you're perversely getting some value for your money, as long as you don't think too hard about the RTX 5090's original $1,999 MSRP.

ROG Edition 20 combo: $10849.96
This frankly ridiculous bundle includes all of Asus' ROG Edition 20 kit, including the ROG Astral RTX 5090, ROG Crosshair X870E, ROG Thor Titanium III 3000W PSU, and the ROG GR20 open-frame PC case. No discount, but the RTX 5090 is the cheapest you'll find it, in the oddest way.View Deal

Yes, the GPU is an unstoppable force for any gamer. Our GPU benchmarks make that very clear. The RTX 5090 is the best GPU you can buy, and no other consumer GPU is going to beat it. It has 21,760 CUDA cores and 22GB of GDDR7 VRAM, with a 512-bit memory bus and bandwidth speeds of up to 1,792 GB/s.

This Astral is a world-beater of its own, though. It features an upgraded design, with a second BTF power connector to pull up to 800 watts, a glass backplate, and a curved OLED screen. It has faster clocks, hitting 2,750 MHz, with a 4.7-slot design. Performance-wise, the OG Astral is beating world records, so this is a card that you can really push to its limits (if you're not scared of charred power cables).

GPU Benchmarks Hierarchy performance charts
Tom's Hardware
GPU Benchmarks Hierarchy performance charts
Tom's Hardware
GPU Benchmarks Hierarchy performance charts
Tom's Hardware

The $6,000 GPU aside, you're also getting a $3,299 Asus ROG Crosshair X870E Edition 20 motherboard. Asus has a few variants of this, but the Edition 20 board here has (alongside some beautiful gold accents) supports for up to nine M.2 SSDs, with five slots on the board and more via add-in cards. There are six USB-C ports, plus two 20 Gbps front-panel connectors. Large copper VRM heatsinks work with its integrated AIO cooler, with a curved 6.7-inch AMOLE screen and a huge copper heatsink. Probably overkill, but for $3,299, you want it all.

You're also getting a $899.99 Asus ROG Thor Titanium III 3000W Edition 20 power supply. It's a PSU, but 3000W isn't to be sniffed at, and it'll certainly provide enough power for the monstruous Astral RTX 5090. It’s fully modular, with another OLED display (magnetic, this time) which you can mount either side, or extend with a cable.

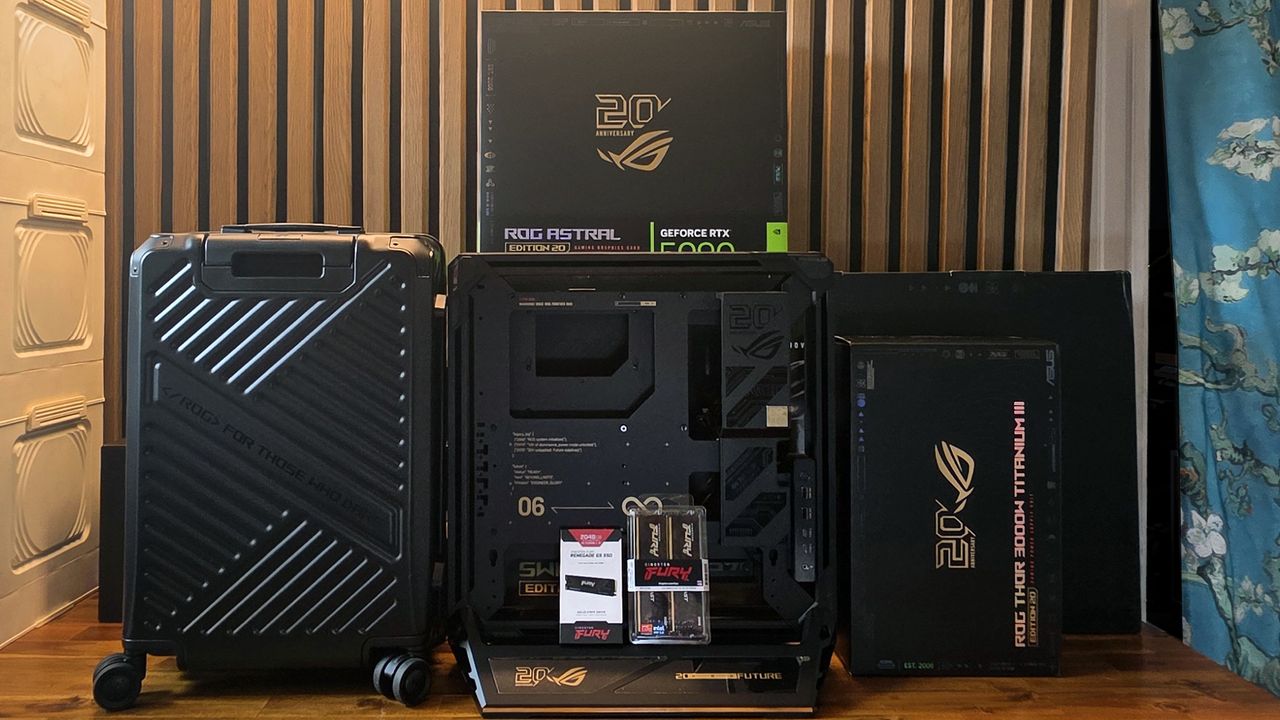
Asus ROG Edition 20 build

(Image credit: Tom's Hardware)

Finally, you get the Asus ROG GR20 open-frame EATX PC case, set at $649.99. This is a totally new design from Asus, supporting large EATX motherboards, and you can stand it vertically or horizontally. There's a crossflow fan to blow cool air onto the GPU, RGB light strips, and several fast USB ports. It's mostly aluminum, with some plastic, magnetically attached cosmetic covers around the sides.

$10,849.96 for this Asus combo kit is so much money for anyone to spend on a gaming PC build, but, unfortunately, we are where we are. As our Asus ROG Edition 20 build write-up mentions, this is a kit that few will buy and own. AI is pushing gaming PCs to new heights, and it's a real shame that we're now seeing current-gen flagship GPUs like the RTX 5090 becoming so rare to buy that combo offers like this are, perversely, almost good value. If you're spending $6K or more on a GPU, though, then it might make sense. You won't find an RTX 5090 cheaper (or, probably, at all, at least for some time) so if you want the best gaming PC build that you can find, this is the kit you'll want. For once, we don't imagine this will sell out soon, but Newegg might pull the deal at any point.

✇Tomshardware

Intel reportedly cans 12Xe option for Nova Lake-S desktop — gaming APU design said to resurface with Razor Lake

作者 Jake Roach

Intel won't launch a Nova Lake-S SKU with 12 Xe3P graphics cores, according to tipster Jaykihn, who originally flagged a beefed-up APU design with the Nova Lake architecture. The original SKU was said to come with 4 P-cores, 8 E-cores, and 4 LPE-cores, along with the 12 Xe3P cores, presumably offering an inexpensive onramp to a gaming desktop without a discrete GPU. Now, the leaker says that design is cancelled, and Intel intends to pick it back up with Razor Lake, the generation that will follow Nova Lake.

Nova Lake -S 12Xe has been changed to Razor Lake -S 12XeSeptember 14, 2026

Originally, Intel's 12 Xe3P Nova Lake SKU was said to require 65W of dedicated power to drive the iGPU, necessitating the use of two VCCGT phases on the motherboard for integrated graphics. Intel's Arc B390 GPU, which is the 12 Xe3-core model available in Panther Lake and Arc G-series processors, has a thermal design that can sustain up to 80W. However, it's currently being used in Panther Lake machines and handhelds like MSI Claw 8 EX AI+ that have lower power targets.

The Xe3P architecture is slotted for use in Intel's Crescent Island AI accelerator, but it hasn't been announced for any other products yet. Xe3P supports a wide deployment of Xe cores (up to 32), a deeper XMX engine with support for low-precision data types like FP8 and FP4, an increased 512KB L1 cache per Xe core, and a new unified L2 cache (32MB on Crescent Island).

Even by desktop APU standards, an 80W iGPU is a beefy accelerator to have on the same package. In addition, Intel's Nova Lake stack is said to extend up to a 175W TDP with the rumored top-end 52-core SKU, meaning the full 12 Xe3P iGPU would likely only be possible lower down the stack (and maybe only in the 4 + 8 + 4 + 12 Xe design originally suggested).

Earlier in the year, rumors suggested Intel was working on a mobile APU to counter AMD's Strix/Gorgon Halo products, featuring a large pool of unified memory and a large iGPU, dubbed Nova Lake AX. Now, the rumor mill suggests Intel will recycle the Nova Lake CPU cores for Razor Lake AX on mobile while pushing a larger iGPU.

Nova Lake-S rumored specifications

SKU*

Core Config (P+E+LPE)*

bLLC*

TDP (Unlocked/Locked)*

52 Cores (dual-tile)

(8+16)+(8+16)+4

288MB

175W

44 Cores (dual-tile)

(8+12)+(8+12)+4

264MB

175W

28 Cores

8+16+4

144MB

125W

28 Cores

8+16+4

-

125W / 65W

24 Cores

8+12+4

132MB

125W

24 Cores

8+12+4

-

125W / 65W

22 Cores

6+12+4

108MB

125W / 65W

22 Cores

6+12+4

-

125W / 65W

16 Cores

4+8+4

-

65W / 35W

12 Cores

4+4+4

-

65W / 35W

8 Cores

4+0+4

-

65W / 35W

6 Cores

2+0+4

-

65W / 35W

*Specs rumored, unconfirmed by Intel

Intel has told us that Nova Lake is one of the most important desktop CPU launches for the company ever, following on the heels of the mediocre Arrow Lake rollout. Perhaps the biggest addition to the lineup is rumored to be bLLC, or big last-level cache, which is said to show up on select SKUs to counter AMD's X3D assault among the best CPUs for gaming. The company has yet to confirm that bLLC is even possible with its current packaging capabilities, though enthusiast channel VP Robert Hallock hinted to Tom's Hardware that Intel has plans to address X3D in the next generation.

The main stack is rumored to climb up to 28 cores, with two additional dual-tile SKUs that can go as high as 52 cores. The dual-tile models look like a bid for HEDT, perhaps competing with AMD's Threadripper CPUs, though it's not clear how Intel will position its dual-tile models yet.

Earlier this month, a leaked slide gave us a glimpse into Intel's launch plans for Nova Lake. The slide suggested Intel will announce the main stack (up to 28 cores) in Q4 of this year, with the chips arriving in Q1 2027. Intel will apparently follow up later in the year with the 52-core model. This aligns with what we've heard from our sources about Intel's Nova Lake rollout.

Alongside Nova Lake, Intel will introduce the new LGA1954 socket, along with the flagship Z990 chipset. We've already seen multiple Z990 motherboards in the flesh, suggesting Intel is preparing for a Nova Lake release in short order.

❌